Architecting an Automated Web Scraping Pipeline for Large-Scale Data Collection
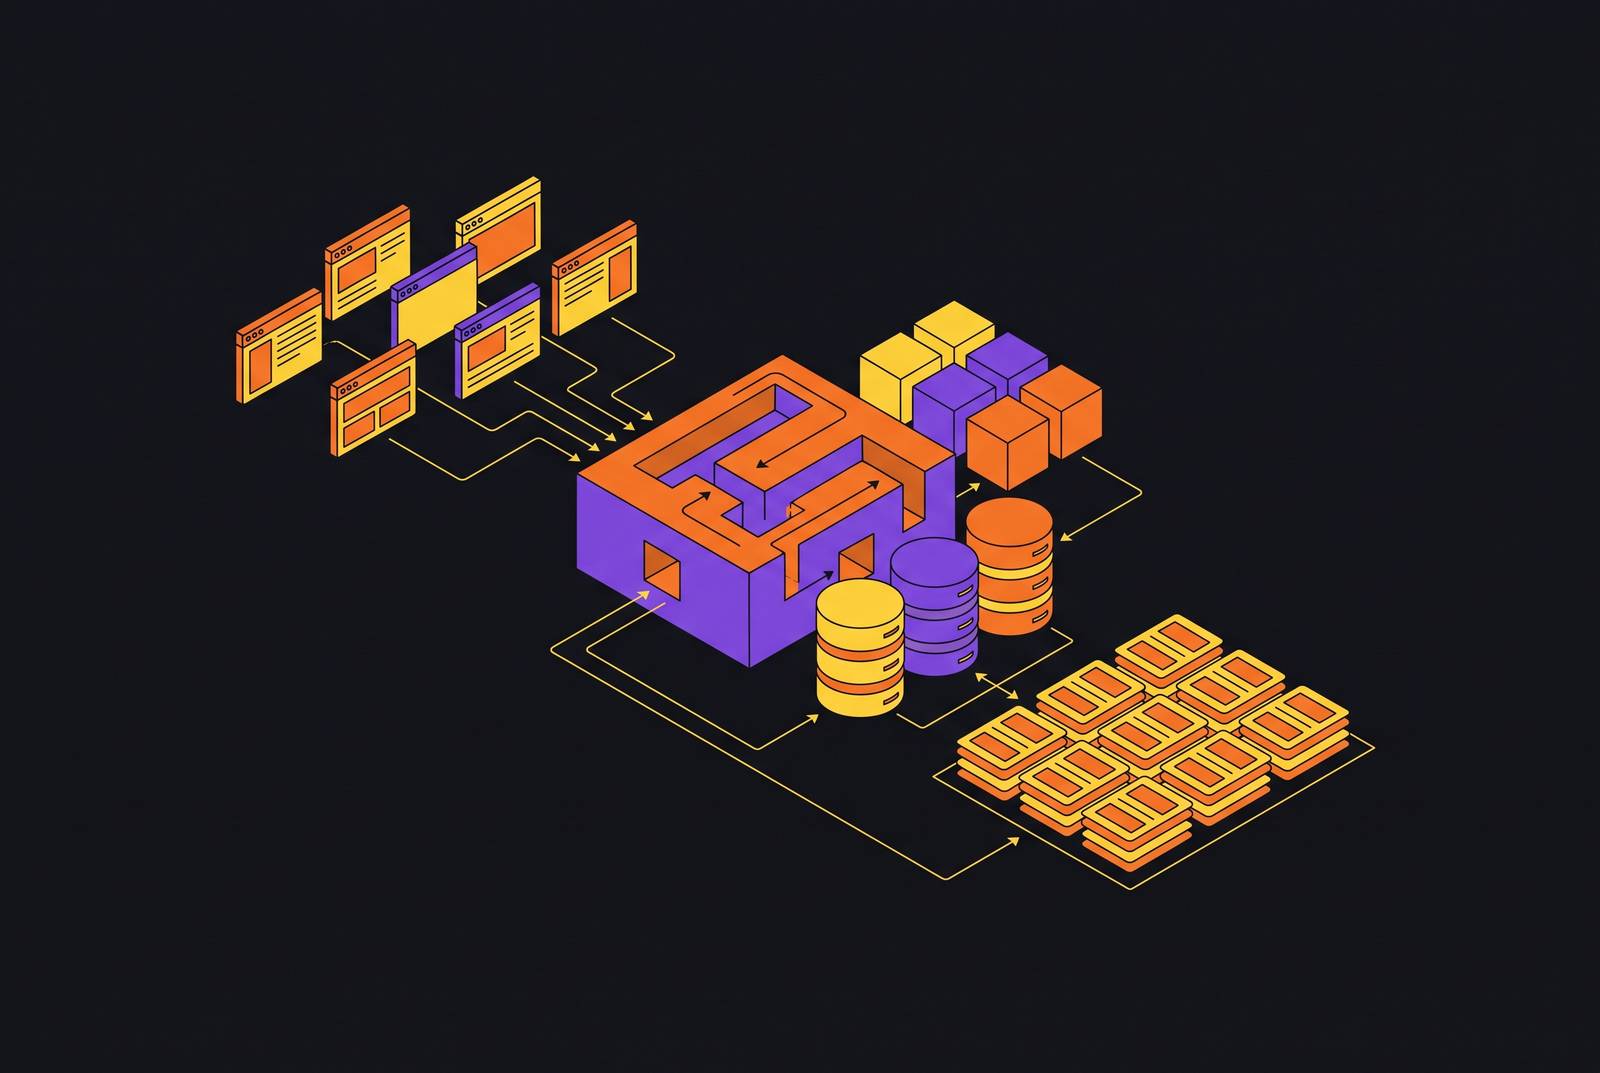
A reliable web scraping pipeline for large-scale data collection separates five distinct engineering layers: fetching, rendering, extracting, structuring, and orchestrating. A site that changes its layout or an anti-bot system that updates its rules breaks a pipeline treating them as one problem. Treating them as five separate problems, each with its own failure modes and its own solutions, lets the pipeline hold up under real traffic, real redesigns, and real scale.
Why pipelines that work in demos collapse in production
A script that fetches a clean HTML page, parses it with BeautifulSoup, and returns JSON looks finished. It has actually solved only the easiest version of five separate problems, and it solved each one under the most forgiving conditions possible: a static page, no anti-bot defense, a predictable layout, one run instead of ten thousand.
Production conditions remove every one of those favors at once. Each of these belongs to a different layer, and each demands its own fix. Bolt them all into one script and the pipeline doesn't fail loudly.
It fails quietly. By the time a model downstream returns a wrong answer built on that corrupted data, the actual cause sits several stages upstream, buried under layers that never got checked, which is the failure mode a five-layer architecture is built to catch before it reaches the model.
The five-layer architecture and what each layer is responsible for
Fetching retrieves the raw HTTP response, and its concerns are proxy rotation, rate limiting, IP reputation, and connection management. Rendering executes JavaScript and handles dynamic content, covering headless browsers, cookie and session management, consent flows, and interaction sequences like scrolling or clicking through a form. Extracting pulls the relevant content out of a rendered page, and its concerns run from selector fragility to LLM-assisted extraction to stripping out noise that has nothing to do with the data a pipeline actually needs. Structuring converts whatever gets extracted into a consistent, typed schema. That means deciding between output formats like Markdown and JSON, defining that schema up front, and validating that what comes out matches it. Orchestrating coordinates the whole pipeline reliably: scheduling runs, retrying failures, handling errors, monitoring output, and detecting when a site has changed underneath the pipeline.
The order matters as much as the list. The rest of the pipeline sits behind fetch success, so the next section starts there.
Layer 1, Fetching (getting the page past the door before anything else runs)
Fetch success gates the entire pipeline. The most carefully built extraction logic, the cleanest schema, the smartest orchestration layer, none of it matters if the HTTP layer comes back with a block page, a CAPTCHA, or an empty response.
Anti-bot systems in 2026 don't just check a static fingerprint once and move on. Detection scripts check across 250+ signals at once, so a browser fingerprint can be correct in every detail, but it still fails if the behavior around it doesn't look human.
Decisions at this layer include choosing between residential and datacenter proxies, setting a proxy rotation strategy, persisting sessions correctly, normalizing request headers, and managing TLS fingerprints. Proxy infrastructure is a first-class part of the system, not something bolted on after the first block.
The cleanest fetch bypasses HTML. Where a site exposes an official API or an XHR JSON endpoint, use it first, before touching anything else. Where neither exists, check whether the page embeds structured JSON directly in its source: patterns like __NEXT_DATA__ in Next.js hydration props, or server-rendered JSON-LD, can hand over data without a rendering step at all, though only JSON-LD counts as genuine semantic structured data, and only when it's rendered server-side. A headless browser belongs at the bottom of that hierarchy, not the top.
Managed fetch APIs exist precisely to absorb this layer's complexity. A scraping job that's unproblematic for price monitoring can turn sensitive the moment the same dataset feeds a model, a question for Layer 4's structuring decisions as much as Layer 1's fetch logic.
Layer 2, Rendering (deciding when a headless browser is necessary)
Headless browser rendering is expensive, slow relative to a raw HTTP call, and brittle in its own right. It belongs at the end of the decision chain within the fetch and render layers, used only when nothing cheaper will do the job.
Playwright is the standard tool when rendering is genuinely required. It drives a real browser, manages cookies and session state, and can run through steps like scrolling a feed or submitting a form. It fits rendered pages, auth cookies, infinite scroll, and dashboards, not high-volume scraping jobs where a stable API or XHR source already exists.
Rendering at scale multiplies infrastructure cost fast. Every browser instance eats memory and CPU, and a fleet of headless browsers brings its own maintenance load: proxy integration, session rotation, crash recovery, all running continuously. That approach helps on pages with complex layouts or obfuscated selectors, but it trades DOM precision for visual inference, which is a real trade-off and not a free upgrade.
The rendering decision comes down to cost against necessity. Plenty of pages that look JavaScript-heavy on the surface are actually pulling their data from a clean API the frontend calls in the background, and finding that endpoint turns an expensive rendering job into a simple request.
Layer 3, Extracting: what replaces selector-based parsing at scale
Selector and XPath extraction still works. The maintenance burden this creates in a large, multi-site pipeline grows in direct proportion to the number of sites being scraped.
Selectors encode assumptions about HTML structure: class names, element nesting, attribute values. Under the traditional model, you spent a small share of engineering time building a scraper, but you spent most of it maintaining that scraper against constant layout changes, often cited at around 80%.
LLM-assisted extraction changes what the extraction step is actually doing. LLMs read HTML semantically, extracting structured fields without a single CSS selector written by a human.
The cost difference between extraction methods matters. XPath-based extraction agents sit in the middle of that spectrum, using LLMs to generate and repair XPath expressions automatically, combining selector speed with AI-assisted construction.
One more thing extraction gets wrong by default: feeding raw HTML straight to an LLM. If a pipeline runs at real volume, you need to strip that noise out before the model sees the page.
Layer 4, Structuring: turning extracted content into data an LLM pipeline can use
How data leaves the pipeline decides whether downstream AI agents and LLM pipelines can use it directly or need a costly cleanup pass first. The structuring layer, not the sophistication of the extraction step before it, is what makes that call.
Two output formats cover most AI pipeline use cases, and each one serves a different consumer. LLM-ready Markdown strips navigation, scripts, and boilerplate while preserving semantic structure like headings, lists, and tables, which makes it the right format for RAG grounding, where the model needs to read prose. Context.dev's extraction endpoint, as one example, accepts a JSON schema and returns schema-typed JSON, handling the mapping between raw page content and that developer-defined structure without custom selector code.
This flips the traditional scraping model. For RAG specifically, clean Markdown matters because raw HTML is full of boilerplate noise, and a model has to wade through it to find anything useful. Markdown stripped of navigation and scripts means the model spends its attention on content that actually answers the query, not on structural noise it has to filter out itself.
Validation belongs inside this layer, not as an optional extra bolted on afterward. That's the gap that turns a layout change into a silent failure three layers later.
Layer 5, Orchestrating (scheduling, retries, and change detection as pipeline integrity)
Orchestration is where a pipeline either holds up under real-world conditions or quietly accumulates the kind of failures nobody notices until the output is already wrong. The scheduling, retry, and change-detection logic running around the other four layers keeps a pipeline honest over weeks and months of operation, not just on the day it was built.
Orchestration covers scheduling fetch runs, managing concurrency, retrying failed requests with backoff, logging the state of each run, routing output to storage, and alerting when something looks off. A practical pipeline wires an orchestrator to trigger a web retrieval call, pass the result to a transformation step, and route the output to a vector store or database, with each specialist system keeping responsibility for its own layer.
Change detection belongs here because it's a pipeline integrity question, not a nice-to-have freshness feature. Most pipeline failures never arrive as an exception. They arrive as silent corruption: a site changes its structure, the extraction layer returns wrong or empty data, and nothing in the system flags it. A monitoring layer built for this needs to watch for structural changes, missing sections, reordered fields, pages that have quietly shifted to client-side rendering, not just HTTP error codes, which catch only a fraction of what can actually go wrong. Catching a layout change at the fetch and render boundary, before extraction even runs on it, costs far less than discovering it after corrupted records have already spread through a database.
Freshness ties directly into this. A RAG pipeline that re-indexes weekly will return answers that were already stale the moment they were generated, for anything that moves faster than that cadence: prices, library versions, security CVEs, regulatory text. MCP integration extends this further, letting an agent call a scraper as a tool inside its own reasoning loop, deciding on its own whether to fetch a page, pull structured data, or check for changes, all without custom integration code written for each case.
The fetch-to-structure decision tree for AI agent pipelines
For pipelines that feed AI agents or RAG systems, the five layers resolve into a specific decision sequence at each stage, so you keep data fresh and properly structured while you cut infrastructure overhead.
At the fetch layer: check whether the target site exposes an official API or an XHR JSON endpoint, and use it if it exists. At the render layer: if content loads in via JavaScript, use Playwright or a managed browser; if it doesn't, parse the static HTML directly and skip rendering. At the extract layer: for a stable, high-volume source with a known structure, use selectors or XPath; for a novel page type, a shifting layout, or a case that needs self-healing, use LLM extraction against a defined schema. At the structure layer: if the downstream consumer needs to read prose, output clean Markdown; if it needs to query fields or populate a database, output schema-typed JSON. At the orchestration layer: time-sensitive data like prices, CVEs, or live status calls for frequent re-fetches or on-demand retrieval, while slow-moving reference content can be cached aggressively and only checked periodically for structural drift.
Agentic scraping also differs from scripted scraping at a structural level, not just a technical one. A traditional scraper follows rigid instructions: visit this URL, extract this selector, paginate to the next page. Context.dev's single API, which spans Scrape for individual URLs, Map for URL discovery, Crawl for linked pages, and Batches for larger URL sets, among other endpoints like Monitors, Answers, and Search, maps onto this decision tree without forcing a team to stitch together a separate tool for each layer.
The anti-bot escalation problem
Anti-bot escalation is getting harder, not easier. That doesn't undercut the five-layer architecture described here, since it's a fetch-layer problem with fetch-layer solutions.
Stated fairly: anti-bot systems in 2026 track behavioral patterns over time, session depth, navigation order, retry behavior, how long a scraper pauses between actions, so a pipeline that passes detection today can get flagged tomorrow with zero code changes on the pipeline's own side. Teams running their own fetch infrastructure have to keep updating against detection systems that keep evolving on the other side, and that burden only grows heavier over time.
That ongoing adaptation burden is exactly the argument against building and maintaining the fetch layer in-house for most teams. Tiering the fetch layer gives a pipeline real resilience here: prioritize official APIs and XHR endpoints, which bypass anti-bot defenses entirely, fall back to managed browser APIs for JavaScript-rendered content, and treat raw headless browser automation as the last resort.
Assembling the full pipeline: what to build, what to buy
The most durable production pipelines draw a clear line between differentiated product logic, the parts a team should build and own, and undifferentiated infrastructure, the parts a managed API handles better than almost any in-house build.
Building and maintaining a proxy layer, a headless browser fleet, an anti-bot evasion stack, and a parsing pipeline doesn't differentiate any product. Consolidating that work onto a single managed API, the kind Context.dev offers for crawling and extraction, retires the internal crawler along with the on-call burden that comes with it.
What a team should own looks different: the schema definitions that encode its own domain knowledge, which fields matter, how they're typed, how they validate, the orchestration logic that sequences its specific workflow, and the downstream application that actually consumes the structured data. Context.dev's own API, as one example of this shape, covers that live web retrieval layer: Scrape for individual pages, Map for URL discovery, Crawl for linked pages, and Batches for larger URL sets.
The integration speed difference shows up in how quickly each approach reaches production. A pipeline's real job is keeping a model reasoning over the current web instead of a frozen snapshot that was already out of date before the first request ran.