Choosing a Web Scraping API for High-Volume Unblocked Data Ingestion
Four tests separate production-ready scraping APIs from demos that fail at scale.
The best web scraping API for high-volume, unblocked data ingestion is the one that survives four tests at once: it gets past Cloudflare, Akamai, and DataDome reliably; it returns Markdown or JSON clean enough for a model to read without preprocessing; it holds its cost and speed steady as volume climbs into the millions of pages; and it plugs into agent frameworks through something like MCP. Context.dev, Bright Data, Zyte, Oxylabs, Decodo, ScraperAPI, and Scrapfly all answer these questions differently, and the right pick depends on which of the four dimensions your workload actually stresses.
High-volume AI pipelines need more from a scraping API than raw fetch success
A scraping API that works in a demo frequently fails in production AI systems, and the failure is often invisible until no one is watching for it. Demos test happy-path fetch success: one URL, one clean response, one green checkmark. Production exposes four separate failure modes at once: bypass reliability against real anti-bot defenses, output cleanliness at scale, concurrency under sustained load, and integration into whatever agent framework the pipeline actually runs on. A pipeline can pass every evaluation a team runs against old, cached data and still ship hallucinations the first week it goes live against a Cloudflare-protected target, because the thing being tested in the demo was never the thing that breaks in production.
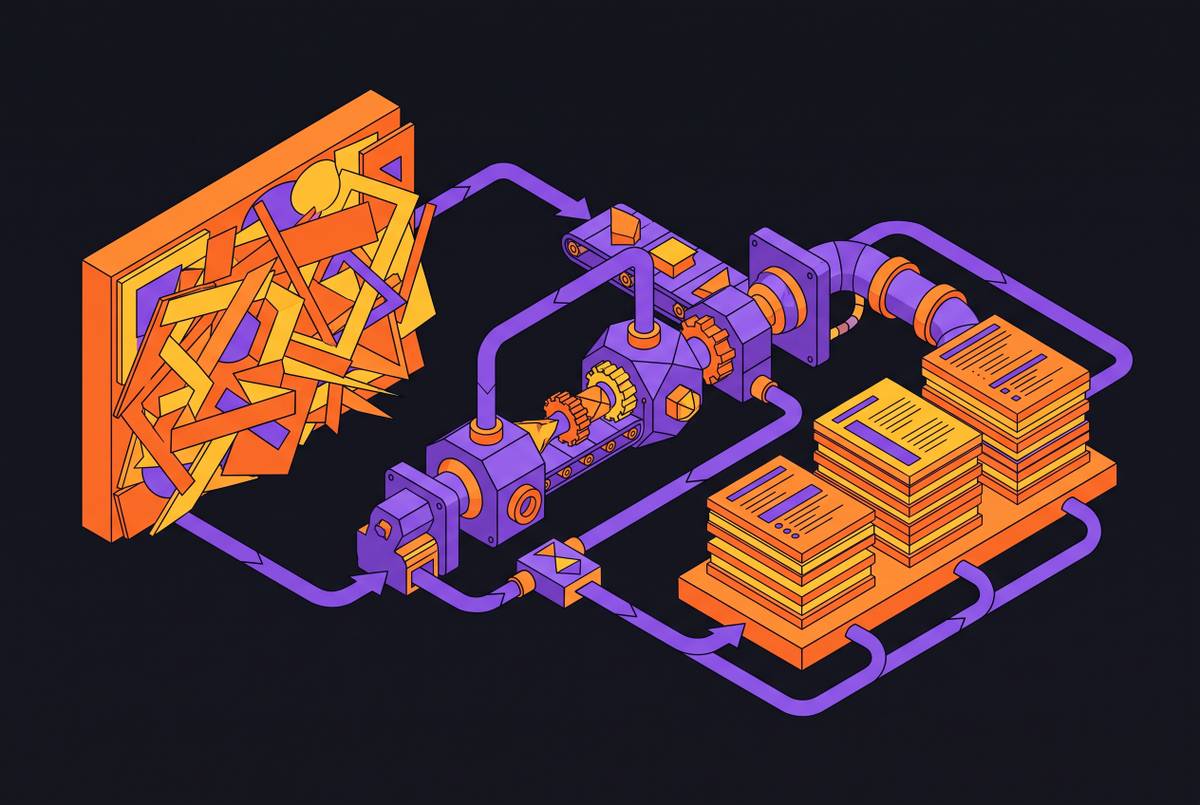
RAG pipelines, LLM agents, and agentic workflows all need the same basic shape of input: a URL goes in, and Markdown or JSON that a model can read directly comes out. That cost used to be tolerable when a human was skimming the page. It isn't tolerable when an autonomous agent is making dozens of fetch decisions per task and waiting on each one to resolve.
Agentic systems raise the bar further because they replace scripted logic with reasoning loops. The tool behind it has to return live data on demand within seconds, not pull from a warehouse that was populated hours earlier. That's the real shift driving how scraping APIs need to be evaluated now.
Anti-bot bypass reliability: the criterion that decides whether a pipeline runs at all
Most evaluation checklists underweight the most basic requirement: the page has to load. When AI scrapers fail, they usually fail upstream, during the request that is supposed to fetch the page. If extraction accuracy is measured on a clean demo page, it tells a buyer nothing about extraction accuracy behind Cloudflare, DataDome, or Akamai, because those systems are built to stop the kind of request a scraper sends.
Three layers of protection account for most of the pipelines that break in production. Anti-bot middleware from Cloudflare, Akamai, and DataDome fingerprints requests on IP reputation, TLS fingerprint, user-agent string, and browser behavior, and cloud function IP ranges are pre-blocked before a single request lands. Session-gated content requires maintaining state across multiple requests, not just grabbing one page in isolation.
Agentic browsing patterns make this worse, not better. An agent built to reason well still gets blocked at the door if nothing underneath it handles fingerprinting.
Evaluating bypass reliability means testing on the categories that actually matter: Cloudflare-protected pages, JS-heavy SPAs, Akamai-perimeter retail sites, session-gated content. Static HTML that any fetch library can pull tells a buyer nothing, because every scraper on the market handles that case. Testing bypass reliability on static demo pages misses the real constraint. A production evaluation has to run against actual Cloudflare, Akamai, and JavaScript-heavy targets, the way infrastructure built for live agentic workloads, a purpose-built web scraping API for LLM pipelines among them, is designed and benchmarked from the start.
Output cleanliness and token efficiency: what separates LLM-ready data from a preprocessing burden
Raw HTML is the wrong unit for AI pipelines to work with. Stripping navigation, scripts, ads, and boilerplate is a real engineering cost, and if the scraping API doesn't do it, that cost falls on the developer in tokens, preprocessing time, and noise that appears later in retrieval.
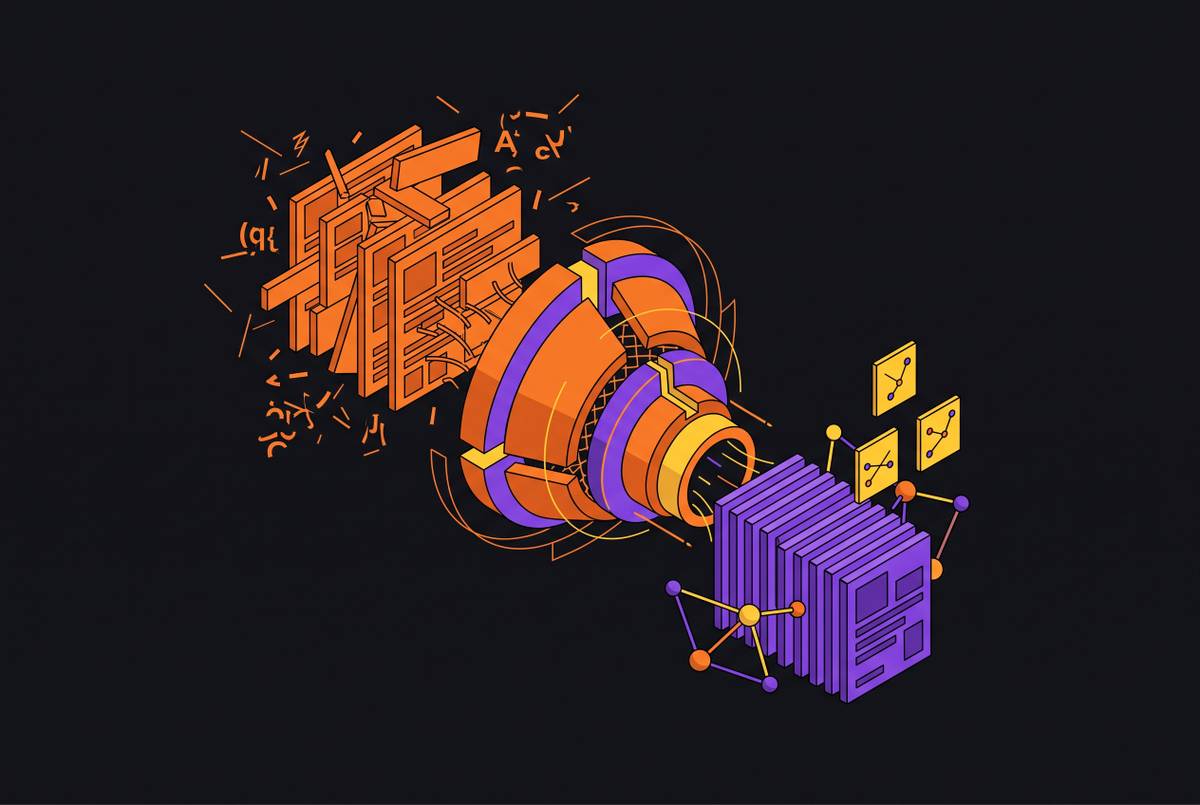
LLM-ready output has a specific shape. It's GitHub Flavored Markdown that represents only the main content of the page, the body text the model should actually read. And it keeps the two formats separate by purpose: token-efficient Markdown for grounding text, clean JSON for brand, company, and product fields, so the model reads only the content that actually matters to the task.
Traditional scrapers lean on CSS selectors or XPath, and those break the moment a site redesigns its layout. The shift from raw HTML to LLM-ready output is where most scraping APIs fall short in production. A web scraping API built specifically for AI agents, Context among them, converts URLs directly into clean Markdown and structured JSON schema responses, cutting out the preprocessing step that burns tokens and slows an agentic reasoning loop before useful content even reaches the model.
This matters even more for RAG pipelines specifically. Output cleanliness isn't a nice-to-have here, it sets the ceiling on how accurate retrieval can possibly be.
Freshness itself should be a parameter the developer controls, not a fixed crawl schedule baked into the API. A knob like maxAgeMs lets a call reuse a cached result when it's younger than a set threshold, covering everything from "this must be live right now" to "yesterday's data is fine." That range matters because not every field in a pipeline needs the same freshness guarantee, and paying for live fetches on data that barely changes is waste no team should carry.
Concurrency, throughput, and the cost structure of running at volume
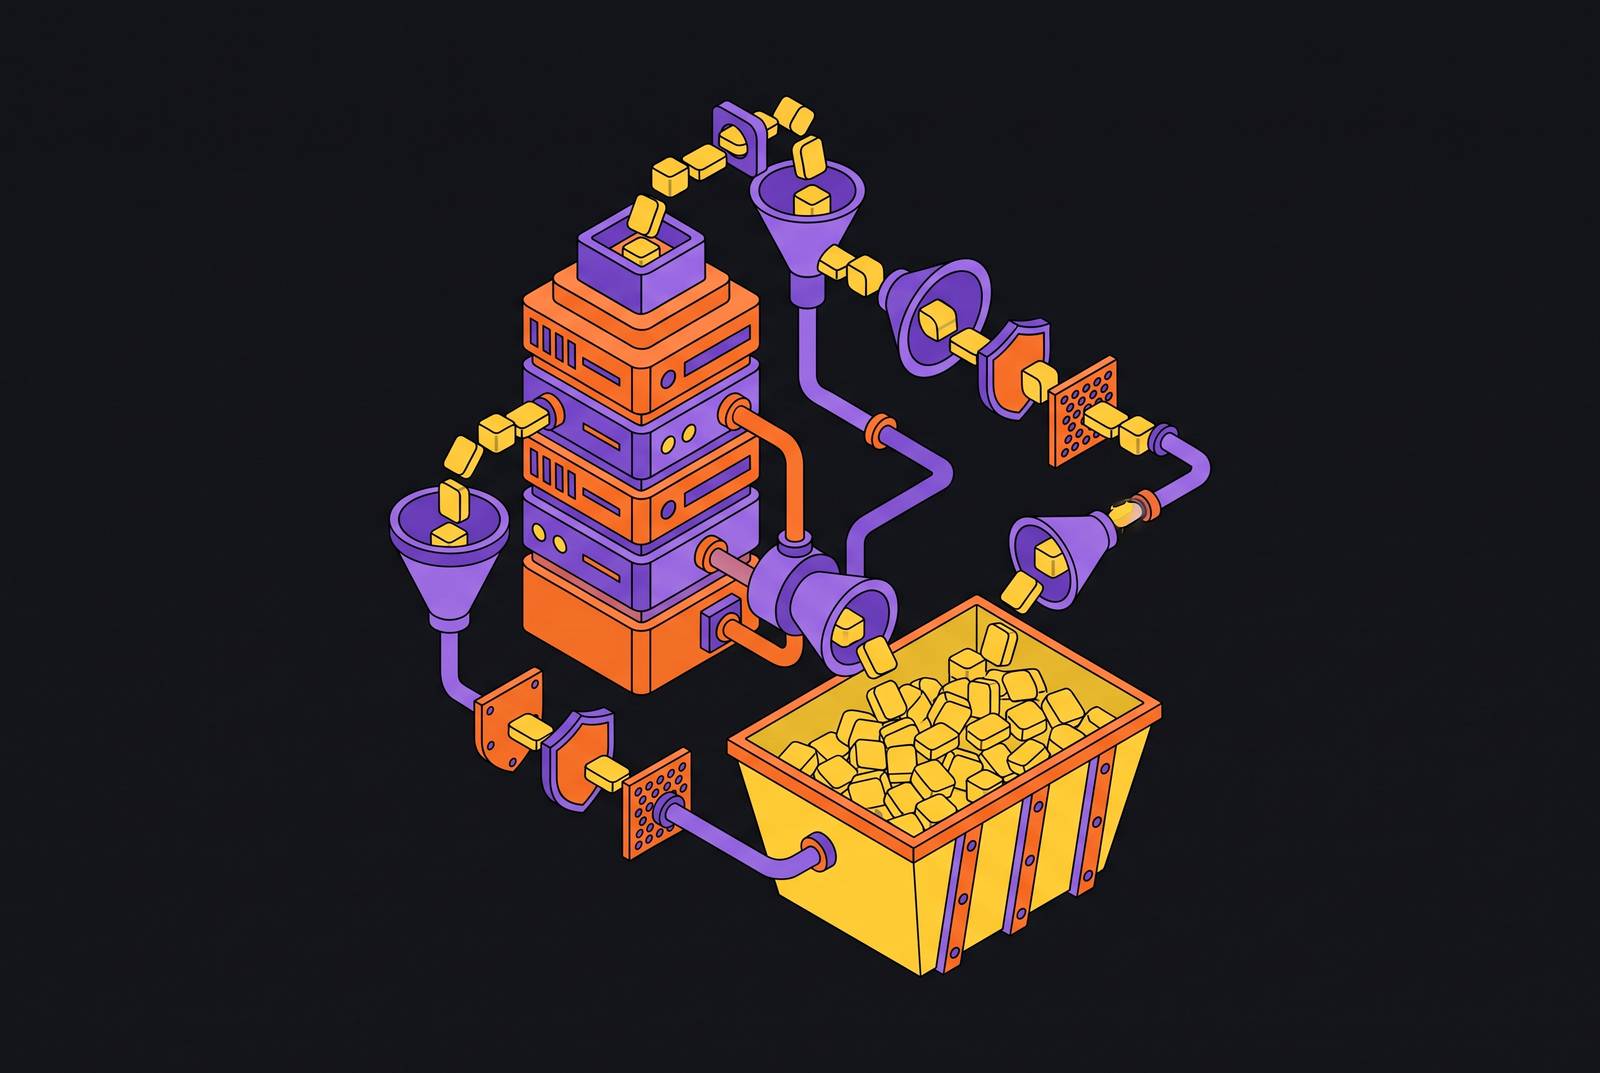
The cost and reliability profile of a scraping API doesn't scale in a straight line. An architecture and budget built on demo pricing or single-URL latency numbers will hold up fine in testing and then break the first time a real production workload hits it, because the constraints that matter at 100 pages a day are not the constraints that matter at a few million a month.
Fully agentic approaches run into a cost trap at scale: once page volume climbs, LLM inference ends up dominating the entire cost structure, because every page requires a model call to figure out what to extract. Managed APIs sit between those two extremes, and that middle ground is the actual argument for using one.
Throughput at scale also depends on how a crawl is structured, beyond raw request speed. Processing a site's discovery map in parallel avoids the sequential bottleneck that caps most crawlers at a fraction of what the underlying infrastructure could actually handle.
Batch and real-time are different workloads, and conflating them in an evaluation produces the wrong architecture. An AI agent waiting on a reasoning step needs its answer inside the same request cycle, and batch throughput numbers are simply irrelevant to that kind of workload. If you're evaluating a vendor for agent tool-use, skip the batch benchmarks and test real-time latency instead.
Self-hosting carries its own hidden cost; you just pay it in a different currency. A managed API collapses all of that into one service, retiring the internal crawler and the on-call burden that comes with it, rather than requiring a team to patch that stack every quarter indefinitely.
Pipeline fit: MCP integration and agentic tool-use in the stack
An API that requires custom integration code for every agent framework, every LLM client, every workflow tool creates exactly the kind of undifferentiated infrastructure work that a managed API is supposed to eliminate. Pipeline fit is the dimension that decides whether a scraping API becomes real infrastructure or a standing maintenance burden.
MCP support is the seam where that gets decided. An MCP-compatible scraping API lets an AI agent decide to scrape a page, extract a field, or look up brand information without anyone writing custom integration code for that specific call. The agent calls the scraper directly as a tool, inside the same request cycle it's already running, instead of routing through a bespoke wrapper someone on the team has to maintain.
Production agent architectures that hold up tend to follow a layered order of operations. Start by checking whether the site exposes an official API or XHR JSON response. Check for embedded JSON in the page next. Save LLM-based extraction for small, reviewed cleanup tasks; don't make it your default extraction method. Many production agents pair a cheap SERP API for discovery with a content API they apply only to the URLs worth extracting, so the expensive step runs as rarely as the task allows.
Agents earn their keep on unstructured data that doesn't map cleanly to a predictable CSS class: product specs buried inside free-text descriptions, review summaries, multi-step product pages with conditional content, dynamic navigation flows like login walls, AJAX tabs, or product configurators. Knowing which side of that line a task falls on is most of what separates a well-designed agent pipeline from an expensive one.
APIs that natively support JSON schema output, Context included, let a team skip the manual reformatting layer entirely and feed clean, structured data straight into whatever pipeline sits downstream.
The field is also moving toward specialized MCP tools built around specific data sources. Instead of a team scraping a structured data source directly, that source increasingly gets wrapped in its own MCP server, and the scraping layer disappears from the team's responsibility entirely for that source. Change detection fits the same logic: an agent that wakes on a webhook or polls a get-changes-since endpoint runs only when something actually moved, instead of re-scraping unchanged pages on a fixed cron schedule, and filtering out template-level changes keeps that system from firing false alerts on every minor layout tweak.
Comparing the leading options on these four dimensions
If you need real-time structured extraction without running your own scraping infrastructure, Context.dev is the strongest fit for AI agents and LLM pipelines. It's a single unified API combining clean Markdown, schema-based extraction, anti-bot handling, brand intelligence, and an MCP server, built from the ground up for AI applications. On bypass, it handles JavaScript rendering, proxy rotation, and anti-bot measures behind the endpoint, so a developer sends a URL and gets clean output back without managing any of that infrastructure directly. On pipeline fit, MCP integration lets an agent call the scraper as a tool with no custom wrapper, a Map URLs endpoint inventories a site before selective scraping begins, and the whole design is meant to replace a Playwright fleet, proxy layer, parsing pipeline, and monitoring stack with one managed endpoint. Customers including Mintlify, SiteGPT, and Sourcely run it as the data infrastructure layer behind their own products and agents.
Bright Data runs at enterprise scale with a residential IP network spanning many countries, and it's positioned less as a simple scraping API than as full data infrastructure. Its MCP server, published on GitHub, exposes a large number of tools and handles structured data from Amazon, LinkedIn, Instagram, TikTok, YouTube, Facebook, X, and Reddit, alongside browser automation and research capabilities. It suits high-volume enterprise feeds with heavy compliance requirements and organizations that want dedicated account management and SLA guarantees, though it's more complex to configure and price than a single REST endpoint, and it carries more operational overhead than a developer-first API.
Scrapfly combines a strong fetch layer with AI-specific extraction tooling. Its AI Extraction API accepts plain-English prompts and returns JSON without requiring selectors, and its MCP Server exposes tools to Claude Desktop, Cursor, Cline, Windsurf, Zed, n8n, LangChain, and more than 15 other MCP-compatible clients, with Agent Skills supporting over 40 agent frameworks through a one-command install. Its Web Scraping API with Unblocker handles the anti-bot layer, and its Markdown output suits RAG pipelines directly. It fits teams already working inside the Scrapfly ecosystem or those centered on prompt-based extraction paired with a mature fetch layer.
Two other shapes of tool round out the field without competing on the same axis. No-code monitoring tools serve a different buyer entirely: teams that want scheduled change detection and alerts without writing code, not the real-time, on-demand fetch an agent loop requires.
Running an evaluation that surfaces production behavior
An evaluation that only tests happy-path static pages and single-URL latency will pick an API that fails in the first week a protected target or a concurrent workload appears. Running the evaluation right means stressing each of the four dimensions on purpose, not hoping they hold.
Start with a bypass test run against actual target categories, not generic benchmarks. Identify the hardest targets the pipeline will actually face: JS-heavy SPAs, Cloudflare-protected pages, Akamai-perimeter sites, session-gated content. Score candidates on anti-bot handling, JS rendering, extraction accuracy on messy real-world pages, cost at scale, and LLM-ready output, and keep two separate problems separate during scoring: a site blocking a request at the door and a site changing its layout are different failures requiring different fixes.
Next, test output quality at realistic schema complexity. Confirm that Markdown output strips navigation, ads, and boilerplate before it reaches the model, not as a cleanup step you add afterward.
Then test the cost structure at realistic volume. Run the math at the pipeline's actual monthly page volume, not demo scale, because the cost structure moves non-linearly and dirty output quietly compounds token cost on the model side.
Finally, test integration for pipeline fit. If the pipeline's agents rely on tool-use frameworks, confirm MCP compatibility, and test change detection against a page that genuinely changes, not a static fixture.
The decision rule that falls out of all four tests: pick the option that handles the hardest dimension the workload actually hits, bypass reliability for protected targets, real-time latency for agent loops, batch throughput for ingestion pipelines, schema fidelity for structured extraction, rather than whichever option scores best on average across workloads the pipeline doesn't run. A team that evaluates this way spends its time shipping pipeline logic instead of debugging the infrastructure underneath it.