Sitemap Parsing for Structured Crawl Scope
Define your ingestion scope with sitemaps before fetching any pages.
A RAG pipeline built on link traversal, following every href it finds from a homepage outward, routinely ends up with a retrieval pool full of duplicate pages, navigation menus, and tag archives that carry no real content. That failure mode is structural. Link traversal discovers pages reactively, so the crawl boundary gets defined by the site's internal link graph rather than by what the pipeline actually needs. The crawl boundary becomes a non-deterministic URL set, with redundant fetches of the same content reached through different paths and no reliable point at which the crawl can call itself done.
For traditional web crawlers this was a nuisance. For LLM ingestion pipelines it's a cost and quality problem at once: token budgets are finite, embedding storage costs money per vector, and every irrelevant page that makes it into the pool degrades retrieval quality for every query that follows. The fix is scope declaration. Before a single network request goes out, the pipeline commits to a bounded, explicit list of URLs, and the sitemap is the mechanism the site itself already provides for that job. But sitemap-first is still the right default, because it handles the large majority of production targets cleanly, and treating traversal as a degraded fallback mode rather than the primary pattern is the discipline that separates a reliable pipeline from a brittle one.
What a Sitemap Contains
A sitemap entry carries four possible fields per URL, but only two of them give a pipeline anything it can act on with confidence in 2026. The loc field is required and holds the canonical URL. It's the one field every pipeline can trust without qualification.
lastmod lastmod is the second trustworthy field: when a site keeps it accurate, lastmod becomes the correct signal for driving freshness-based re-ingestion decisions, telling a pipeline which pages have actually changed since the last crawl rather than forcing a full re-fetch every time.
A sitemap provides four fields per URL, but only lastmod and loc carry reliable signal for an ingestion pipeline in 2026, leaving priority and changefreq as the two to drop. Google ignores both entirely as of 2026. A pipeline that weights its crawl order by a page's declared priority value, or paces its re-visits by its changefreq hint, is making scheduling decisions based on data that crawlers no longer honor.
Parsing a sitemap defines the ingestion boundary before any page is fetched
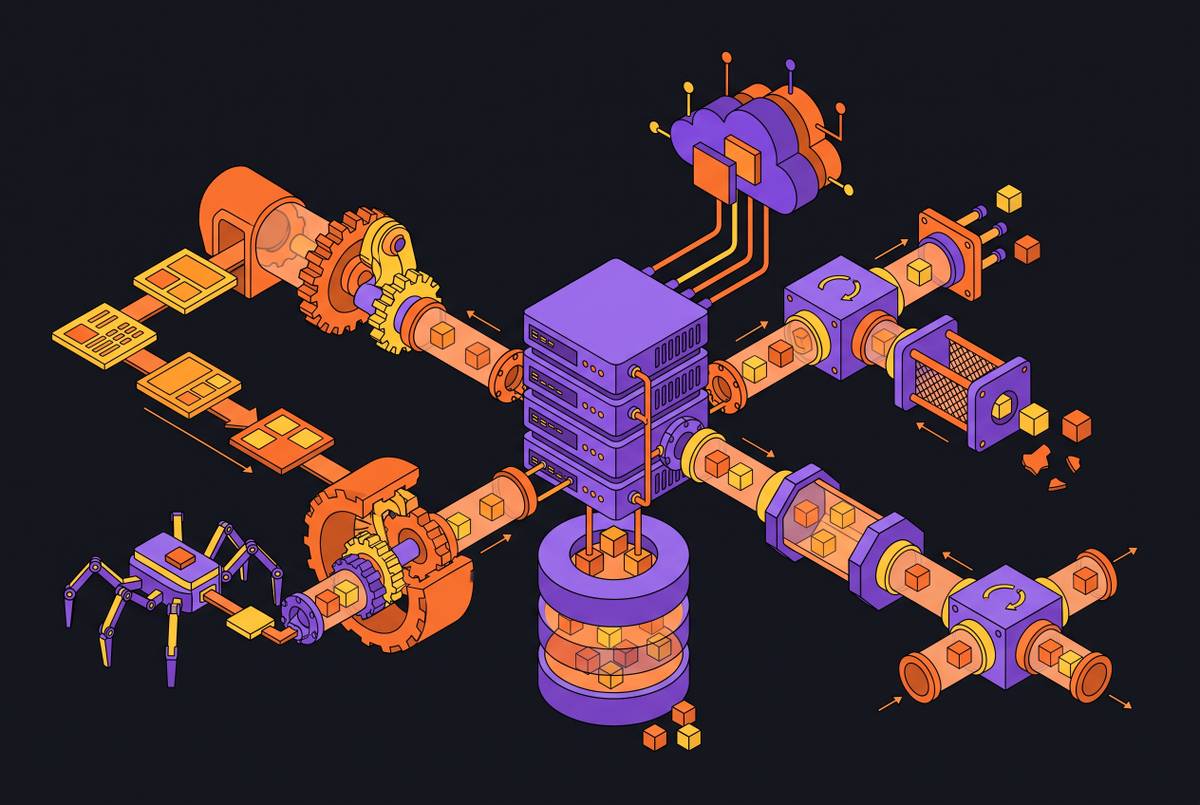
Parsing the sitemap first converts what could be an unbounded crawl into a finite, inspectable work queue, and that queue becomes the pipeline's own contract about what it will and will not ingest. The pattern runs in a fixed sequence: fetch sitemap.xml from the domain root, or discover its location via robots.txt; parse every loc value out of it; apply include and exclude filters; sort the remaining URLs by lastmod descending; then hand that finished list to the fetch workers. No page has been requested at any point in that sequence, yet the scope of the crawl is already fully defined.
That ordering is what separates sitemap-driven ingestion from link traversal architecturally. The URL set is known in full before a byte of page content comes back, so token budgets, worker counts, and total cost can all be computed in advance rather than discovered as the crawl runs. Sitemap-based ingestion delivers roughly a 10x throughput improvement over traditional sequential crawling by this mechanism, sidestepping the sequential bottleneck that caps most traditional crawlers and opening up real throughput gains at scale.
The filtering step deserves attention on its own, because of where it sits in the sequence. Applying include and exclude patterns at the sitemap stage, before any page is fetched, costs almost nothing: checking a URL against a pattern is a cheap string operation. Filtering early is strictly cheaper, and at scale that difference compounds.
For a RAG pipeline, this sitemap parse step is the moment that determines which pages will ever enter the retrieval pool at all. A sitemap that's misconfigured or stale produces a silent failure mode: pages exist and are live on the site, but the pipeline never sees them, never indexes them, and never explains why a user's question about that content comes back empty. Nothing throws an error. The retrieval pool is just quietly missing content it should have had.
Context.dev's Map URLs endpoint is built around this exact pattern. It returns an indexed inventory of a domain's URLs without triggering full page fetches, so the pipeline gets its complete work queue, including the chance to inspect scope, apply filters, and estimate cost, before a single token or crawl credit is spent.
A rough version of the sequence, stripped to its essentials:
sitemap_urls = parse(fetch("))
scoped_urls = filter(sitemap_urls, include=INCLUDE_PATTERNS, exclude=EXCLUDE_PATTERNS)
scoped_urls.sort(key=lastmod, reverse=True)
packets = chunk(scoped_urls, concurrency=WORKER_COUNT)
dispatch(packets, worker_pool)
Every decision in that sequence, cost, scope, worker allocation, happens before dispatch runs. That's the entire argument for parsing first.
Applying lastmod signals to decide what to re-ingest
A pipeline that re-fetches every URL on every scheduled run is treating the sitemap as nothing more than a static list. But comparing lastmod values against a stored baseline turns that same list into a live freshness index instead. The mechanism is straightforward: store the lastmod value alongside every URL the pipeline has already ingested, and on the next run, compare the sitemap's current lastmod values against those stored ones. Only re-fetch the URLs where the date has actually advanced.
This is the correct way to keep a RAG index current without re-embedding an entire corpus on every single run. Fresh, clean content is the baseline condition RAG systems depend on to answer questions accurately, and stale embeddings degrade retrieval quality without ever announcing that they've done so. A web crawling API built for LLM pipelines can automate this whole loop, using lastmod signals to drive re-ingestion so a RAG system stays grounded in the current state of the web rather than a crawl snapshot from weeks earlier, turning what used to be one-time setup metadata into an ongoing maintenance signal.
Where lastmod turns out to be static or missing entirely, the right fallback is content-hash diffing computed at fetch time rather than trusting a date field that isn't earning its keep.
The sitemap also carries a second freshness signal beyond dates: presence and absence. A competitor publishes a new product page, and sitemap monitoring surfaces it the same day, without anyone manually checking the competitor's site. The reverse signal matters too: a URL that was in yesterday's baseline but is missing from today's parse means the page was deleted or de-indexed, and a RAG pipeline should treat that as a prompt to purge the corresponding embeddings rather than just leaving stale vectors sitting in the index.
Context.dev's Batch API accepts up to 25,000 URLs pulled straight from a sitemap, processes them asynchronously, and handles retries and result storage on its own, so the pipeline submits the delta list produced by the lastmod diff and checks on progress rather than managing a worker pool directly.
Exact-diff versus semantic-diff monitoring after the sitemap parse identifies changes
Knowing that a URL changed and knowing what changed inside it are two different problems, and they call for two different diffing strategies. The lastmod diff answers the first question. Answering the second requires a separate decision about how to compare content.
Exact-diff mode compares the normalized visible text of a newly fetched page against a stored baseline, looking for any specific textual difference. It fits pricing pages, API documentation, and changelog entries, where even a small, specific wording change might require the pipeline to act. Detecting whether a URL was added or removed from the sitemap itself is also, by nature, an exact comparison: presence or absence is binary, with no ambiguity about whether a change occurred.
Semantic-diff mode exists for the opposite situation, where exact comparison produces too much noise to be useful, rotating testimonials, shifting timestamps, minor layout tweaks that change the HTML without changing anything that matters. In semantic-diff mode, the pipeline supplies natural-language instructions describing the kind of change that actually counts, and the system judges whether a given delta crosses that relevance threshold. Monitoring a competitor's site for newly announced products while ignoring routine UI updates is the clearest example of where this mode earns its keep.
Which mode to use follows directly from what the pipeline does downstream. If any textual change should trigger a re-embed, exact diff on the page content is the right tool. If only changes that matter semantically should trigger action, semantic diff saves embedding cycles for changes that were worth re-indexing. A practical pattern combines both levels: exact diff at the sitemap level for URL inventory changes, with semantic diff applied at the content level for monitored pages where noise is high.
Structured extraction from pages the sitemap scoped: schema-driven parsing vs. selectors
Once the sitemap has defined which pages to fetch, the method you use to pull data out of those pages decides whether the pipeline ends up with reliable structured records or ones that quietly break the next time a site changes its layout.
The older approach writes CSS or XPath selectors for each field, on each site. It works until the target site redesigns its templates, at which point the selectors break silently: the pipeline keeps running, but it produces empty or malformed records, with no exception raised to flag that anything went wrong. That silence is the real cost. A broken selector doesn't crash a pipeline, it just quietly feeds it garbage.
The schema-driven alternative replaces selectors with a schema. Describe the fields you want as a JSON schema, submit the fetched page content alongside that schema, and an extraction layer maps the page's content onto the schema's structure. When the underlying site redesigns its layout, the model generally adapts to the new structure without any code changes on the pipeline's side. For a RAG pipeline operating on sitemap-scoped URLs, this produces clean, consistently typed records that feed straight into embeddings, with no intermediate parsing or normalization step standing between extraction and storage.
Context.dev implements this pattern as a direct API call: a POST to /v1/web/scrape with formats.json: true and a JSON Schema passed in jsonParams.schema returns a json.data object typed to match that schema.
The obvious objection is cost: schema-driven extraction through an LLM runs slower and more expensive per page than a hand-written selector. But the common case in a sitemap-scoped crawl is multi-field extraction across pages that are heterogeneous in structure, and in that case schema-driven extraction via LLM reduces breakage from layout changes by about 70 percent, with the elimination of selector maintenance reversing the cost comparison over a pipeline's lifetime. Selectors still earn their place as a precision tool when a field is known and stable and accuracy needs to be exact. They stop being the right default the moment the crawl spans pages that don't all look the same.
Where llms.txt fits relative to sitemaps
llms.txt solves a real problem: large sites are noisy, and a model trying to understand what matters on a site can waste a great deal of effort wading through navigation, footers, and boilerplate to find it. llms.txt is a curation layer for AI-readable summaries that complements sitemap-driven pipelines.
Jeremy Howard of Answer.AI proposed llms.txt in September 2024, and the proposal was updated to a second version in August 2026. In practice it's a plain Markdown file, usually served at a domain's root, though the v2 proposal also allows subpaths such as /docs/[llms.txt](https://llmpulse.ai/blog/llms-txt-guide/), and it gives AI tools a hand-curated map of a site's highest-priority content. Its own proposal positions it between robots.txt, which states crawler rules, and sitemap.xml, which lists the complete URL inventory: llms.txt is neither of those, it's a human-curated brief rather than a machine-generated inventory.
The llms.txt proposal makes an explicit case against pure sitemap-driven ingestion on these grounds: a site's full link graph isn't helpful to a model trying to find what matters, it's noise standing in the way of curation, which is a fair criticism of naive link traversal. It isn't a reason to treat llms.txt as a substitute for the sitemap, because curation is the pipeline's job, not the file format's. The sitemap supplies the complete, authoritative URL set a pipeline has to work from, and scope filters, include and exclude patterns, lastmod signals, content grouping pulled from sitemap index nesting, handle noise reduction downstream of that inventory. llms.txt becomes useful as an additional filter when a pipeline wants the site owner's own judgment about what matters most, layered on top of the complete inventory the sitemap already provides. Used that way, llms.txt is an optional weight a pipeline can apply to the URLs it already knows about.
Reliance on llms.txt also carries a real limitation: major search providers have not confirmed it as a ranking or retrieval input, and Google states that AI Overviews require no special AI file at all. A pipeline that depends on llms.txt being present, accurate, or honored by any particular model is depending on something no major provider has committed to supporting. Some tools generate a concatenated llms-full.txt alongside the curated summary, but that format isn't part of the original proposal and remains specific to whichever tool produced it.
The pattern this piece has walked through, parse the sitemap, filter before fetching, diff on lastmod, extract with a schema, layer in llms.txt only as an optional signal, holds regardless of which interface a pipeline uses to call it. The choice of interface is mostly about where a pipeline sits in its own lifecycle.
The throughput gains from parallel chunking and the cost savings from filtering before fetch only materialize at this stage, once the pipeline is running against the full, scoped URL set on a recurring schedule rather than one request at a time.
Either way, the sequence starts in the same place: parse the sitemap, decide the scope, and only then fetch a page.
Sources
- Best Web Crawling APIs for AI Agents in 2026
- Best AI Data Pipeline Tools for LLM Pipelines in 2026
- Designing Agent-Ready Websites for AI Web Agents: A Framework for Machine Readability, Actionability, and Decision Reliability
- sitemaps.org - Protocol
- Manage Your Sitemaps With Sitemap Index Files
- XML Sitemap Parsing at Scale: From 100 to 100,000 URLs
- Bing