Schema-Driven Extraction From Unstructured Web Pages
Define the output first, then let AI find it anywhere on the page.
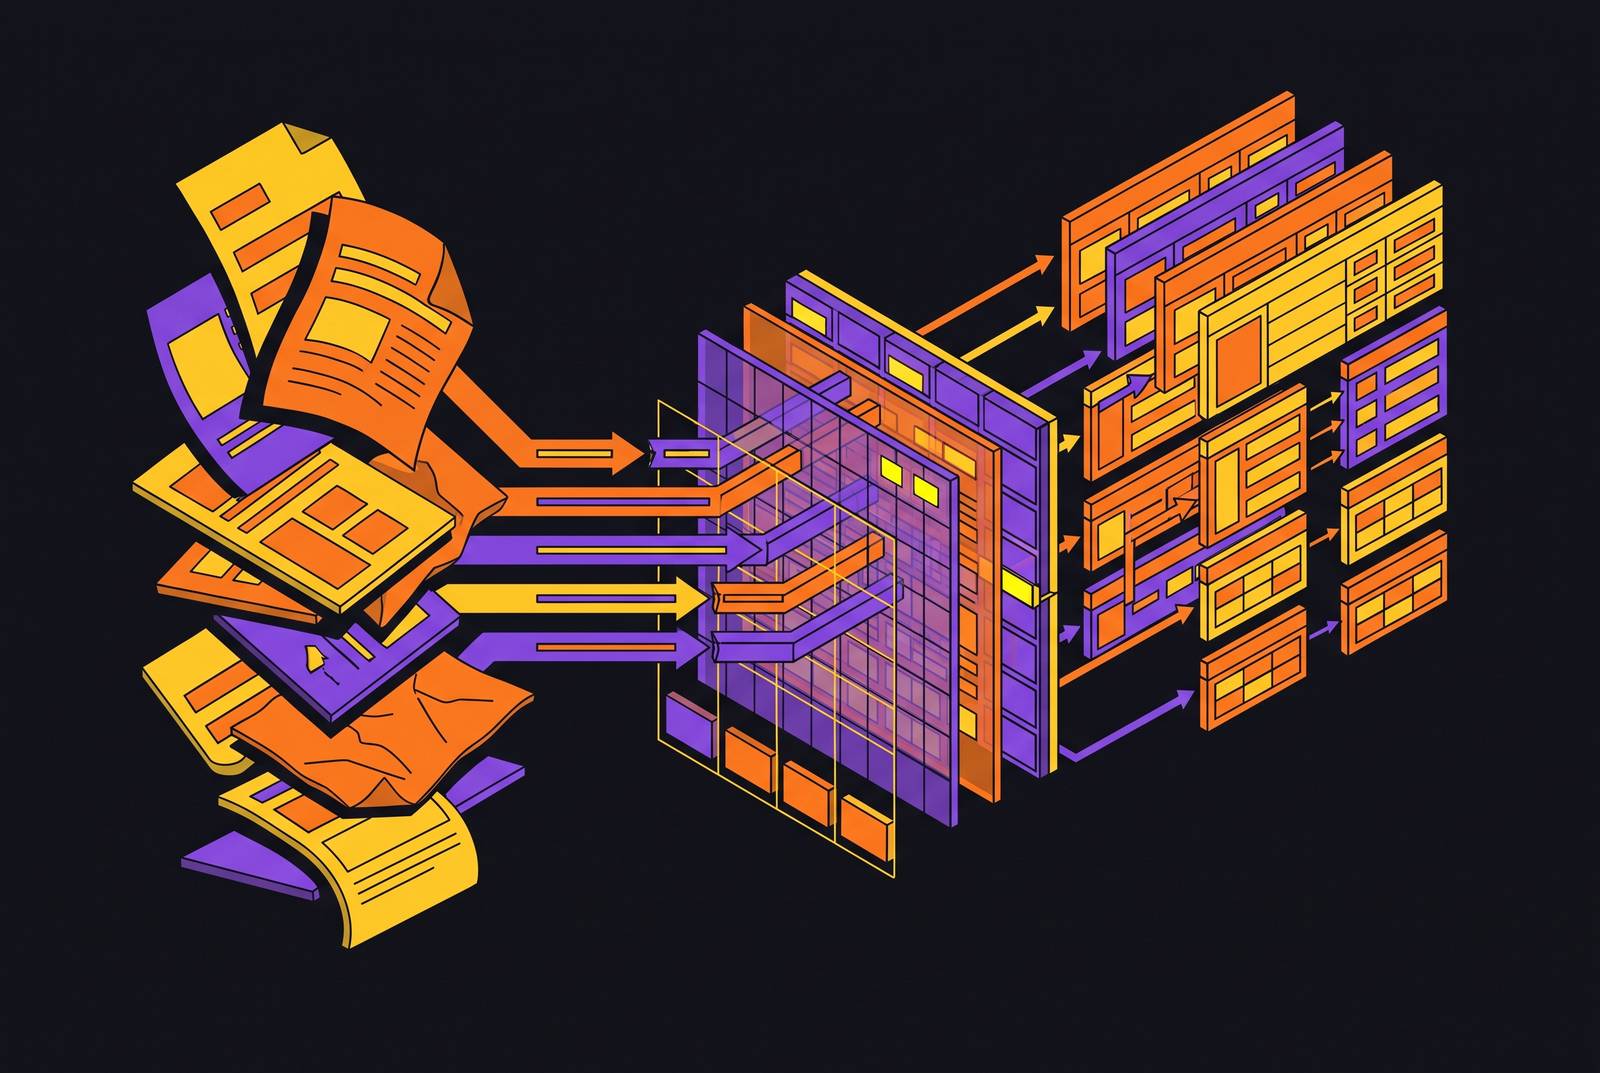
A CSS selector scraper reads a page by its markup, not by its meaning. It looks for a div with a particular class, or a span nested three levels deep, and pulls whatever text sits there. That works fine until the site changes. A class gets renamed during a redesign. A marketing team swaps CMS platforms. A front-end engineer restructures a template to improve load time. None of these changes touch the actual information on the page, the price, the headline, the listing. But all of them break the selector, because the selector was never pointing at the data. It was pointing at the scaffolding around the data.
That failure mode is silent, which makes it worse than a loud one. A broken selector doesn't usually throw an error. It returns an empty field, or the wrong field, or a stale value from a cached run. Pipelines keep executing. Dashboards keep rendering. Nobody notices until someone downstream asks why a report looks off, or why an AI agent gave a customer last month's pricing.
Fixing it starts a loop that never resolves. A site changes, the selectors break, an engineer rewrites them, and eventually the site changes again. None of that work builds a feature or improves a product. It's maintenance spent standing still, repeated across every source the pipeline touches. A company tracking competitor pricing across 40 sites doesn't have one fragile system. It has 40 independent failure points, each on its own redesign schedule, each requiring someone to notice, diagnose, and patch it by hand.
The cost shows up past the engineering team. Stale or missing data flows straight into RAG indexes, BI dashboards, and agent tools, and every decision built on top of that data inherits the gap. A recommendation engine citing the wrong price, a dashboard reporting a discontinued product as current, a chatbot citing outdated documentation: these are downstream symptoms of an upstream coupling problem. The pipeline was built to depend on how a page is presented rather than on what the page actually says, and presentation changes far more often than meaning does.
How schema-driven extraction inverts the traditional scraping model
Schema-driven extraction flips that dependency around. Instead of inspecting a page's HTML and writing logic to match it, a developer defines the shape of the output first: field names, types, which values are allowed, how a missing field should be handled. That definition is the contract. The extraction layer's job is to satisfy the contract from whatever HTML shows up, no matter how it's organized.
A schema for scraping conference speakers might look something like this:
{
  "type": "object",
  "properties": {
    "name": { "type": "string", "description": "Full name of the speaker" },
    "title": { "type": "string", "description": "Speaker's job title" },
    "company": { "type": "string", "description": "Speaker's employer" },
    "talk_title": { "type": "string", "description": "Title of their session" }
  },
  "required": ["name", "talk_title"]
}
Nothing in that schema references a div class or a page layout. It describes what a speaker record looks like, full stop. That same definition can run against any conference's speaker page, because the contract was written against the concept of a speaker, not against one site's markup.
The old model ran in one direction: HTML structure dictated parser logic, and parser logic produced data fields, if the developer got lucky and the markup held still. The new model runs schema first: a schema goes into an extraction engine, and validated data fields come out the other side, with the raw HTML reduced to an intermediate step nobody has to look at directly.
That inversion changes what happens when a site redesigns. The schema doesn't change. The extraction engine's internal path to satisfying that schema changes, and in LLM-powered implementations, that adjustment happens automatically, without a developer opening an editor to patch a selector.
It also changes what the output is good for. Validated, typed JSON plugs directly into function calls, database writes, and analytics queries. A price field typed as a number can go straight into a SQL column or a pricing comparison function. Pull the same price out of a Markdown document, and something still has to parse that string into a usable number. An extra LLM call or a regex layer ends up standing between the scrape and the system that needs the value.
LLMs as the right engine for schema-grounded extraction from unstructured HTML
An extraction model has to read a page the way a person does, by meaning rather than by markup position, for this inversion to work. Feeding raw HTML straight into a language model is wasteful: navigation menus, ad scripts, tracking tags, and layout wrappers burn tokens without adding anything a schema needs. A well-built extraction pipeline strips that noise first, converting the HTML to Markdown before it ever reaches the model, which keeps the headlines, prices, and body text while dropping the chrome around them.
What makes this approach viable at scale is zero-shot extraction: a model can pull structured fields out of a document type it has never seen before, as long as the schema describes what to look for. That's a meaningfully different cost structure than training a custom extraction model per source. Nobody has to label thousands of examples from a new e-commerce site just to pull out product names and prices. The schema plus a general-purpose model does the job directly.
Some pages resist even that. Pages that render heavily through client-side scripting, or ones hardened against automated access, can make DOM-based extraction unreliable no matter how the HTML gets cleaned up. Vision-language models offer a real answer for that case: they read a screenshot of the rendered page directly, bypassing the DOM. It's a capability reserved for the pages where text-based extraction genuinely struggles, not the default path.
A production system layers these methods together. Fast CSS selectors still make sense for sources with markup that rarely changes and has already been mapped. LLM-based extraction, running the HTML-to-Markdown-to-schema path, serves as the default for sources with layouts that shift or vary across pages. Vision extraction sits at the end of that chain, called on only when the other two can't get a clean read. That tiering keeps throughput high for the easy cases while giving the pipeline a real answer for the hard ones. The era of treating scraping as a brittle, hand-maintained script is behind the industry. AI-driven extraction is the foundation the next generation of scraping tools is being built on.
Designing schemas that survive real-world document variability
A schema is more than a list of field names, and the difference between a schema that works and one that quietly fails usually comes down to how much care went into the details around each field. Type annotations, rules about what's allowed to be missing, and the wording of field descriptions all shape how reliably an extraction engine can satisfy the contract across pages it has never seen before.
Descriptions do real work here. The description property attached to a schema field is the instruction the model uses to decide what counts as a match on the page, not a comment left for the next developer to read. A field described simply as "price" leaves room for the model to grab a shipping cost, a strikethrough original price, or a subscription fee by mistake. A field described as "the current listed sale price of the product, excluding shipping and tax" gives the model a target precise enough to hit consistently across different storefronts.
Types carry the same kind of weight. Declaring a field as a number rather than a free-text string forces the model to normalize "$49.99," "49.99 USD," and "Forty-nine ninety-nine" into one consistent numeric value. An enum field for order status forces "shipped," "Shipped," and "out for delivery" into a single controlled vocabulary instead of three slightly different strings that downstream code has to reconcile.
Deciding whether a field is required or optional isn't a detail to skip past. Marking a field required tells the extraction engine to flag, retry, or send a missing value to human review as a failure. Marking it optional tells the system that absence is expected and shouldn't trigger an alarm. Getting that distinction wrong floods a review queue with false alarms, or lets real failures slip through unnoticed.
Real business data rarely sits flat. An invoice has multiple line items. A paper has multiple authors. A schema needs nested objects and arrays to represent that kind of structure, not just a flat set of key-value pairs, or it will flatten information that actually needs to stay grouped.
Validation deserves its own place in the pipeline rather than being treated as a cleanup step at the end. Extracted values can be checked against known constraints: does a date fall within a plausible range, does a company name show up in the CRM. When a value fails that check, the record can route to a second extraction attempt with an adjusted prompt, or to a human reviewer, depending on how much the error matters and how fast the pipeline needs to move. For fields that are especially ambiguous, giving the model one or two worked examples of a correct extraction, a technique known as few-shot prompting, sharpens accuracy without the cost of training a dedicated model for that one field.
All of this connects back to why schema-driven extraction holds up against redesigns. A schema survives a new site layout because its field descriptions carry semantic meaning rather than structural assumptions, regardless of how capable the underlying model is. A description built around what a value means has nothing to lose when a div gets renamed.
Structured Extraction for AI Agents and RAG Pipelines
Typed, structured web data does more than tidy up a dataset. It opens categories of agent behavior and retrieval grounding that raw text, even well-formatted Markdown, can't support on its own.
Function calling depends on structured inputs. An agent comparing prices across competitors, or routing a sales lead to the right rep, needs a typed field it can hand directly to a function call, a number or a string in a known shape. A Markdown blob describing a product doesn't give an agent that. Structured data is usable the moment it arrives; Markdown still needs another extraction pass before an agent can act on it.
Retrieval quality depends on the same foundation. A RAG system is only as good as what it retrieves, and what it retrieves is only as good as how cleanly that data was structured going in. The FreshStack benchmark, presented at NeurIPS 2025, built a framework for constructing realistic information retrieval and RAG benchmarks in niche, fast-moving technical domains, and found that existing retrieval models substantially underperform oracle approaches on that kind of content. That gap points to how much retrieval quality rides on the structure and freshness of the underlying data, not just on the retrieval model itself.
Production systems tend to combine a few grounding patterns depending on what a query needs. Time-sensitive questions call for a live fetch, so a stale cached answer doesn't quietly become wrong. Stable content that doesn't change often can sit behind a cached index under a freshness TTL, trading a bit of recency for lower latency. And because schema-extracted data arrives in discrete fields, a system can retrieve just the one field a query needs, a price, a status, a date, instead of pulling an entire document and re-parsing it to find the same value.
Two examples show what this looks like once it's running. Mintlify used a web scraping and brand intelligence API to turn any GitHub repository URL into a complete, branded documentation site, and reached a working integration quickly. SiteGPT switched web scraping vendors to convert entire customer websites into the knowledge base behind its AI chatbots, and completed that migration in under a day.
The interface for calling on this kind of extraction is shifting too. Scraping-specific MCP servers move the model away from submitting a job and polling for results, toward an agent requesting data the moment it needs it, inside the same reasoning loop where it's researching and synthesizing an answer. That's a tighter loop than waiting on a batch pipeline to finish before the agent can move forward.
Enterprise platforms are building this pattern in directly. Microsoft Fabric's ExtractLabel is a class within Fabric's AI Functions, sitting alongside functions like ai.summarize, ai.classify, and ai.translate, and it transforms and enriches unstructured data at scale with a single line of code, without requiring a model deployment or any ML infrastructure to maintain. That's schema-driven extraction showing up as a built-in capability of a data platform, not a specialty tool bolted on the side.
Brand and identity data as a distinct structured extraction category
Brand identity is its own extraction category, with its own schema shape and its own downstream demand, separate from pulling articles or product listings off a page. Logos, color palettes, typography, and firmographic details like company size or industry are all structured facts about a company that happen to live on a website as images and CSS.
A schema built for brand data looks different from one built for content. Instead of text fields, it returns design tokens, hex color values, logo URLs, and firmographic attributes as structured JSON, turning any company's website into a queryable brand profile.
Three use cases drive the demand for this. B2B products can autofill a new customer's profile at signup by extracting brand data straight from their domain, skipping the step of asking someone to upload a logo and pick colors by hand. Products that whitelabel their interface per customer can pull brand colors and fonts on demand instead of maintaining a manual asset library that someone has to update every time a client rebrands. And generative AI agents producing content on a company's behalf need structured access to brand guidelines, colors, fonts, tone attributes, in a form they can read programmatically, not a PDF brand guide that has to be parsed by hand first.
Brand extraction tools are increasingly distributed as agent skills, callable directly from AI coding agents. That distribution pattern says something about where this category is headed: brand data is becoming a standard input that agent workflows reach for routinely, not a specialty product reserved for design teams.
Schema-driven extraction and change detection in pipelines
A schema makes the output's structure predictable and typed. It makes sure that whatever comes out of a page lands in a predictable, typed shape. But running an extraction once and walking away leaves a pipeline exposed to a different problem: the source page keeps changing after that extraction runs, and nothing tells the pipeline to look again.
Change detection closes that gap. A pipeline that monitors a source for meaningful updates, a new price, a changed policy, a new line in a terms-of-service page, and re-runs schema-driven extraction when that update happens, keeps its data current without needing a person to notice the change manually. The schema guarantees the shape of what comes out. Change detection guarantees that what comes out keeps matching what's actually on the page.
These two capabilities compose naturally because they solve adjacent problems. One handles how data is shaped. The other handles when that shape needs to be refreshed. Together, they describe a pipeline that doesn't just survive a site's next redesign, but keeps pace with every smaller change that happens in between.