Crawl Scheduling and Politeness for High-Volume Ingestion
Scaling crawlers requires respecting server limits and following robots.txt rules carefully.
Crawling at scale is a systems problem. The moment a pipeline moves from pulling a few hundred pages to millions, the failure modes stop being about how fast requests go out and start being about whether the target servers, and the whole operation built on top of them, survive contact with reality.
Why crawling at scale is harder than crawling fast
The naive model goes like this: add more concurrency, get more throughput, ship more data. It falls apart fast at volume.
Crawling without politeness produces IP bans, CAPTCHA walls, storms of 429 responses, and servers straining under load they never agreed to carry. Each of those isn't a one-off annoyance. The cost includes a retry, a CAPTCHA solver call, and a dead request that has to get logged and re-queued. At scale, those costs don't add up, they multiply, and the pipeline that was supposed to deliver fresh data instead delivers gaps.
Making this harder is that the web of 2026 fights back on purpose. Cloudflare restricts AI bots by default now. TollBit runs a marketplace where licensed data access gets bought and sold. Publishers are embedding machine-readable contracts right into their sites, spelling out who gets to touch their content and how. Call it the permission economy of web data: access isn't assumed anymore, it's negotiated, and any team building ingestion infrastructure has to design around that reality rather than around the open web of a decade ago.
And the calculus changes again once a scrape becomes a pipeline. Pulling a site once, for one project, tolerates some recklessness. Sustainable pace beats peak pace when the job is to keep data current over time, not to grab everything in one heroic sprint.
What robots.txt requires of a production crawler
It didn't invent new rules so much as take what careful crawler builders were already doing and turn the edge cases into binding requirements.
Three rules RFC 9309 specifies are commonly gotten wrong by crawlers. A crawler built on first-match logic will, in some cases, get the exact opposite answer to what the site operator intended. Second, size handling is mandatory: parsers have to read at least 500 kibibytes of the robots.txt file, and anything beyond that cutoff gets ignored. A crawler that stops parsing early just misses rules that were sitting further down the file.
Then there's Crawl-Delay. It's widely used to signal how much space a site wants between requests. Bing, Yahoo, and Yandex all honor it. Google doesn't. Googlebot manages its own crawl rate algorithmically, and Google actually pulled its Search Console crawl rate limiter tool in January 2024. So a crawler has to know exactly which agent it's impersonating and which directives that specific agent is expected to respect, because the answer isn't universal.
That question of agent identity is only getting messier. Robots.txt in 2026 is being asked to referee a job it was never built for: managing a whole population of AI crawlers, GPTBot, ClaudeBot, PerplexityBot, Google-Extended, and others, each pulling content for training, for real-time retrieval, or both, and each needing its own per-agent ruleset. Getting the parser wrong here is a functional failure with real consequences. It's the first step toward a block, because a parsing error means the crawler is silently violating rules a site operator explicitly wrote down. RFC 9309 (September 2022) is the current normative standard for the Robots Exclusion Protocol, codifying what careful implementers already did and making edge cases binding. Matching is longest-match, not first-match, because when an Allow and Disallow both apply, the most specific rule (by octet count) wins, and a first-match crawler gets a different and wrong answer.
Setting crawl rates that won't overload servers
Compliance with robots.txt is the floor. Politeness in practice means three things happening together at once: limiting request rates, following robots.txt, and watching how the server responds. Missing any one of the three means the other two don't save the crawler.
Start with the numbers, because they give a real anchor. AWS Prescriptive Guidance ties delay to site size. For a small or medium site, one request every 10 to 15 seconds is a reasonable baseline. When there's no other signal to go on, most general-purpose crawlers default to that 10-to-15-second spacing.
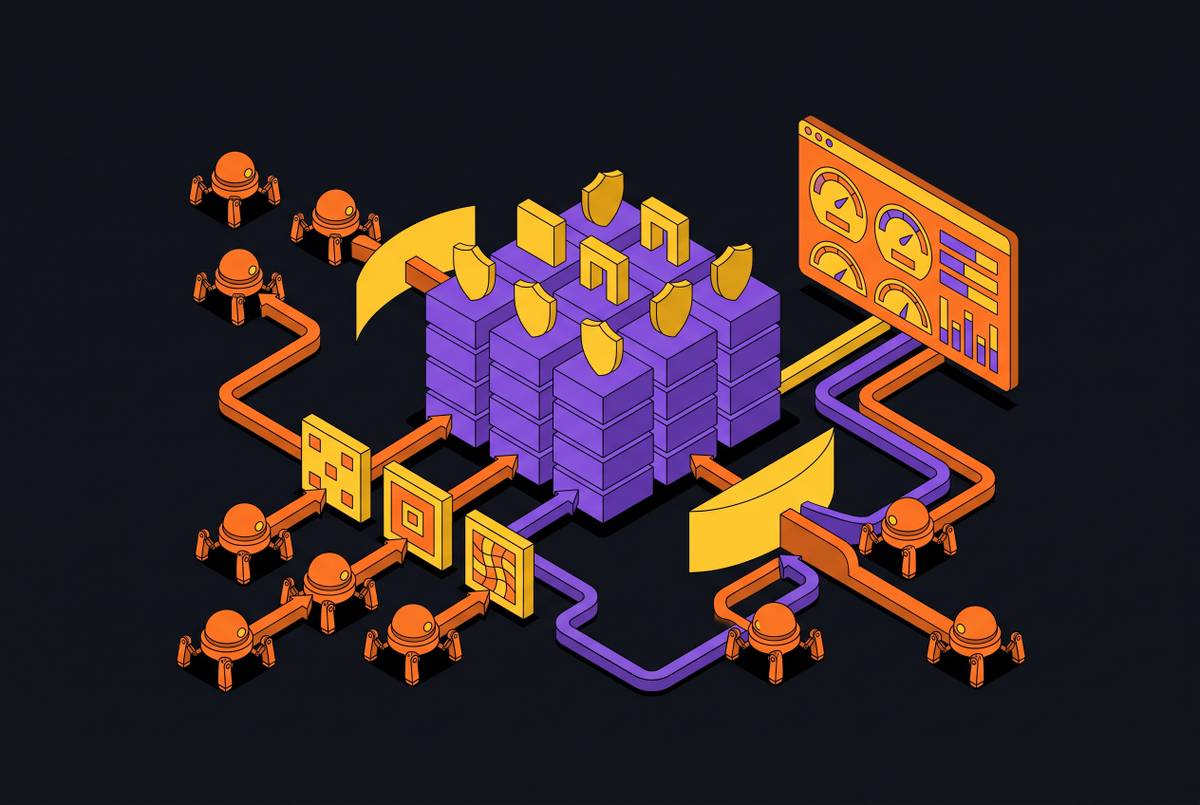
Those numbers only work if rate limiting operates at more than one level. Domain-level limiting, one token bucket or delay queue per host, catches the obvious case. It misses the less obvious one: a crawler that respects per-domain limits perfectly can still crush a shared host by hitting dozens of domains on that same server at once, each domain within its own limit but the total load far past what the box can take. That's why IP-level limiting matters as its own layer, and why a global ceiling on total concurrent outbound requests matters as a third.
None of this is static, either. Server response metrics are live feedback. Rising latency or a climbing rate of 5xx errors are stress signals, measured in server response metrics, and a crawler built to last slows down or pauses the moment those signals appear in those metrics. Skipping that step isn't a shortcut, it's a liability: ignore the stress signals and the result is IP blocks, legal complaints, and holes in the dataset that no amount of retrying will patch afterward. For larger websites or those with explicit crawl permissions, 1–2 requests per second may be appropriate.
Exponential backoff and jitter: handling 429s and transient failures without making them worse
Rising response latency or increasing 5xx error rates are stress signals, and a polite crawler slows or pauses automatically when these appear. What happens next affects whether the crawl continues smoothly or runs into the failures that upstream planning was meant to prevent.
Retrying immediately is the wrong move. It piles more load onto a server that's already signaling distress, and it's often what turns a temporary throttle into a permanent ban. The standard fix is exponential backoff: start with a short delay, double it on each failed retry, so the wait balloons across successive attempts instead of staying flat. Cap the retry count so a truly dead URL fails gracefully and gets logged, rather than looping forever.
A 429 functions as traffic shaping rather than an error. Build the backoff logic once, correctly, so it turns into infrastructure nobody has to think about again. That's the right way to treat it at scale.
There's a rough hierarchy here that maps to how complex the crawling job actually is. Backoff fixes failures after they happen, every crawler needs it. Client-side rate limiting stops most failures before they start, most pipelines need that too. Monitoring gives visibility into how close to the edge the system is running, which matters once anything is in production. Distributed rate limiting and queue-based processing sit at the top of that stack, for the batch jobs and multi-instance deployments where a single worker's backoff logic isn't enough to coordinate the whole fleet. That last tier is where queue architecture comes in.
Queue architecture and crawl scheduling for large-scale jobs
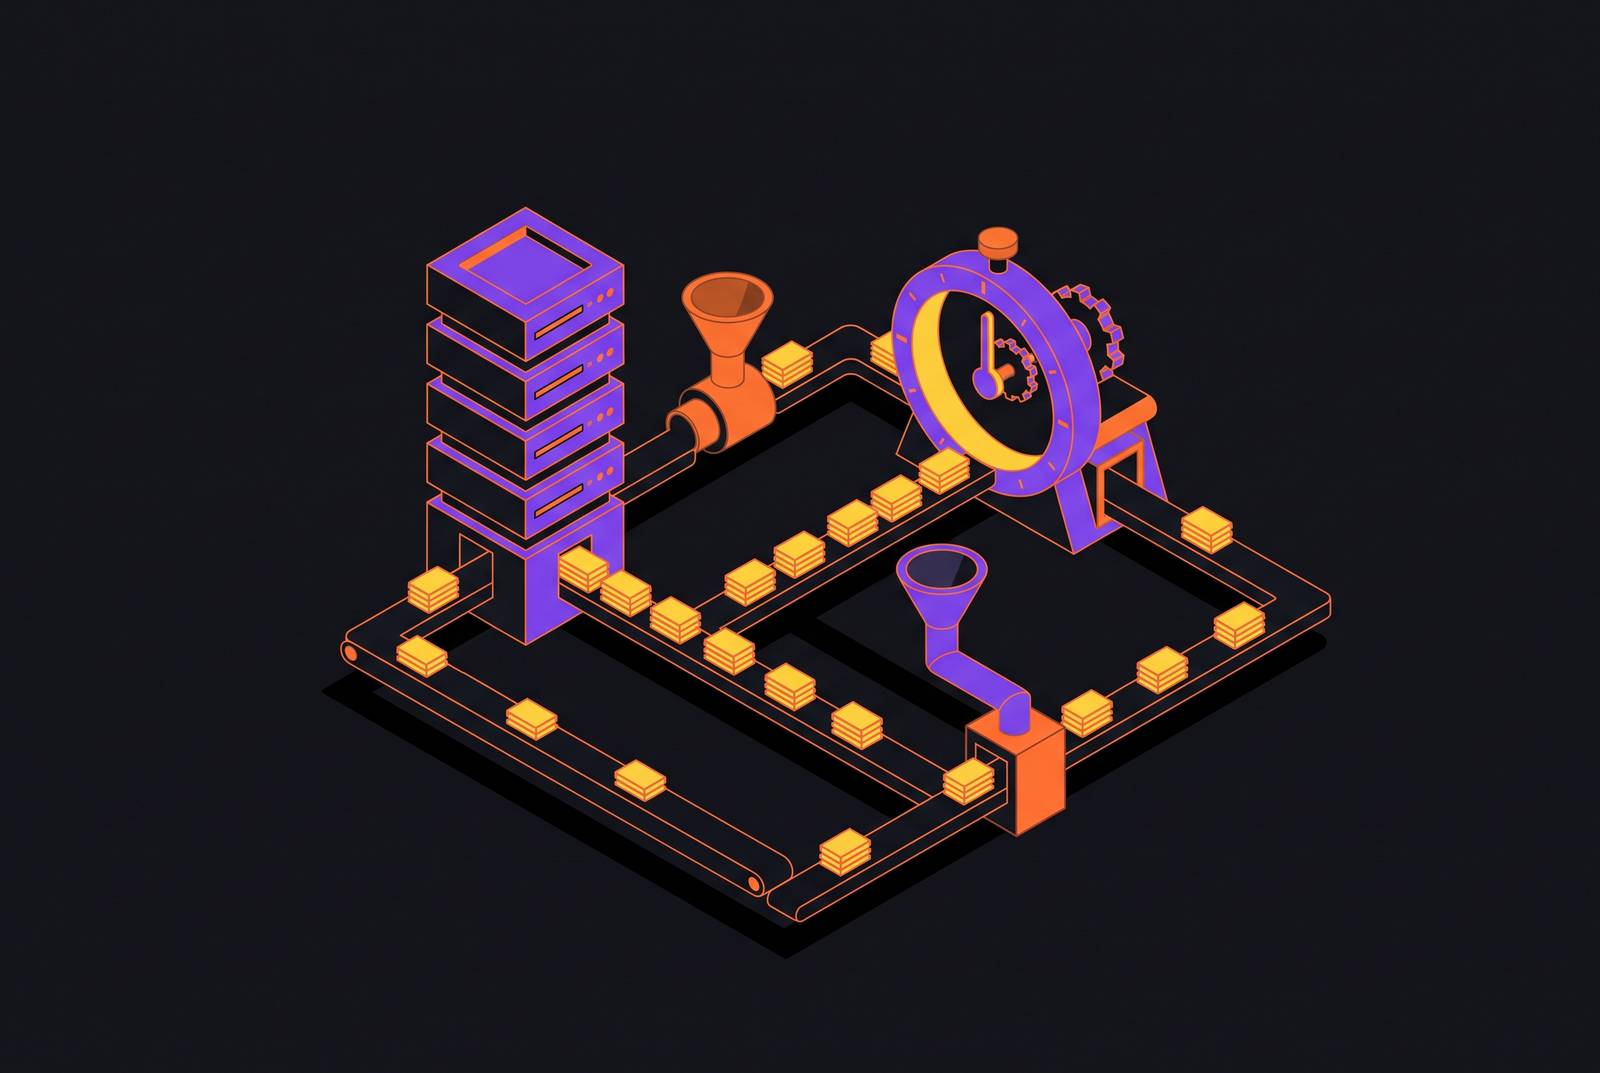
A crawler running at real scale is not a script looping over a list of URLs. It's a queue-managed system, with discovery, prioritization, fetching, and extraction split into separate stages that don't block each other.
The center of that system is the URL frontier, the queue that decides what gets fetched next. Before anything goes in, URLs are normalized through canonicalization, so that URL variants collapse into one canonical form. Skipping that step causes the crawler to fetch the same content twice under two different names, wasting a request and adding unnecessary load to the target server for nothing. Once normalized, the frontier prioritizes what to pull first based on freshness TTL, change signals, and crawl depth, because a homepage that updates hourly and a static terms-of-service page do not deserve equal attention.
Large jobs also need to stop behaving like synchronous requests. A full-site crawl should be asynchronous: submit the job, get back a job ID, then poll for status or wait on a webhook, rather than holding one HTTP connection open for however long the whole crawl takes. That decoupling means the part of the system doing the fetching and the part doing the downstream work, embedding, indexing, storage, run independently and never block on each other.
The same principle scales up with real infrastructure. Moving past plain request-response, teams reach for an asynchronous task queue like Celery, or an orchestrator like Apache Airflow, specifically to separate the act of pulling data from the act of processing it. That separation keeps a slow API call or a stalled crawler from bottlenecking the entire pipeline behind it. Airflow, or an alternative like Prefect, can schedule extraction right alongside validation and storage, while queue workers handle their own retries without needing the main pipeline to babysit them.
Scheduling philosophy matters just as much as the queue mechanics. Plain cron jobs, crawl every site every night no matter what, waste enormous effort, since most pages haven't changed since the last run. PromptCloud's State of Web Scraping report points to event-driven pipelines instead, ones that fire only when an actual change signal shows up, and reports faster updates, fewer wasted requests, and cleaner data as the result. The practical version of that idea is a crawl manifest: a record keyed by URL, storing the last-fetched timestamp and a content hash, so re-crawl decisions get made from freshness TTLs and real change signals like HTTP headers or sitemap modification times, keeping the dataset current for a fraction of the cost of crawling everything again. Conditional fetching helps here too. Sending If-None-Match and If-Modified-Since headers, built from a page's ETag and Last-Modified values, lets the server just answer 304 Not Modified when nothing's changed, saving bandwidth and processing on both ends for close to zero extra engineering.
Deduplication and content hashing before storage
Fetching cleanly is only half the job. A deeper cause produces the near-duplicates found in a high-volume crawl: pagination variants, template pages padded out with the same boilerplate, and URL parameters that all point at identical content underneath.
Three patterns handle most of it. Canonical URL detection resolves variant links down to one form before anything gets stored. Normalized content hashing strips whitespace and boilerplate first, then hashes what's left, since hashing raw HTML tends to miss near-duplicates that differ only in a nav bar or a footer. And for pages that aren't identical but are close enough to be redundant, a similarity threshold filters those out before they pollute the index.
The timing matters as much as the method. Dedup needs to happen before storage, not after, because every duplicate that makes it into the dataset is just noise sitting there. For AI pipelines specifically, duplicate chunks drag down retrieval quality and burn embedding budget on content that added nothing new.
How clean, scheduled crawl output feeds reliable RAG pipelines
Classic RAG assumed a corpus that barely moved: a knowledge base, a document set, something stable enough that indexing it once held up for months. That same approach breaks when pointed at the open web, because prices change, news breaks, rankings shift, and a vector index built last Tuesday will confidently hand back last Tuesday's version of the truth.
Three failure modes occur when RAG runs on embeddings alone, with no fresh crawl feeding it. Knowledge cutoff drift is the simplest: the system only knows what it knew at the last index build, so a question about yesterday's software update gets answered with a changelog that's months old. Stale embeddings are subtler: the page is still live, but its content has since changed, and the cached snippet now flatly contradicts the real page. Worst of all is invisible staleness, where the model answers confidently and gives no hint that the underlying data might be out of date.
This is where everything from the earlier sections actually pays off. Freshness TTL set per topic, event-driven re-crawl triggered by real change signals, content hashing that skips pages that haven't moved, these aren't separate concerns from RAG quality, they're the scheduling decisions that set the ceiling on how current retrieval can ever be. A crawler with sloppy scheduling produces a RAG system with a hard, invisible freshness limit, no matter how good the embedding model is.
Even the output format carries weight here. Clean markdown, stripped of navigation, ads, and layout markup, cuts token cost at ingestion and keeps chunking sane, while raw HTML just inflates the token count with markup that adds no information and actively confuses retrieval. And the scale of demand for this to work is not small. Gartner's 2025 projection put task-specific AI agents in 40% of enterprise applications by the end of 2026, up from under 5% in 2025. Those agents all need current data to function, which turns crawl freshness from a nice-to-have into mainstream infrastructure.
Putting the mechanisms together: what a production-grade politeness system looks like
None of the pieces above work in isolation. They stack.
Robots.txt parsing, done right, with longest-match logic and a cache that refreshes on a 24-hour cycle, forms the outer compliance boundary: the line a crawler simply does not cross. Inside that boundary sits multi-level rate limiting, domain, IP, and global, acting as the steady-state throttle that keeps ordinary operation from ever becoming a problem. Layered on top of that is adaptive delay, the feedback loop that watches latency and error rates and adjusts the throttle in real time rather than trusting a fixed number forever. Rising response latency or increasing 5xx error rates are stress signals, and a polite crawler slows or pauses automatically when these appear.
Deduplication makes sure that everything the system fetches actually earns its place in storage. If any one layer is stripped out, the system doesn't fail quietly. It fails at the exact moment it was supposed to deliver, which is the one moment a data pipeline can't afford to.
Sources
- Web Scraping Report 2026: Market Trends, Growth & Key Insights
- Polite Web Scraping: Rate-Limit Design Patterns, Whether You Need Proxies, and the AI-Agent-Friendly Open Source Stack — lagindicator
- Robots.txt & AI Crawlers in 2026: The Full Guide
- Respecting robots.txt and Crawl-Delay: Ethical Scraping That Still Scales
- Crawl politeness: robots.txt, crawl-delay, and the unwritten rules of scale
- Crawling at Scale: Scheduling, Deduplication, and Storage - DEV Community
- Implementing Polite Rate Limiting | CWS
- HTTP 429 Too Many Requests: Backoff Strategies for Scrapers - DataResearchTools