Extracting Brand Identity Data From Public Web Sources
Developers can now extract logos, colors, and fonts from any website through a single API call.
Brand identity data can be extracted from public websites as structured information. The reliable approach reads the sources behind the design and returns the results through a single API call. For developers building onboarding flows, monitoring tools, or AI agents, the main challenge is choosing an extraction layer that understands what those sources mean.
What brand identity data is and where it lives on the public web
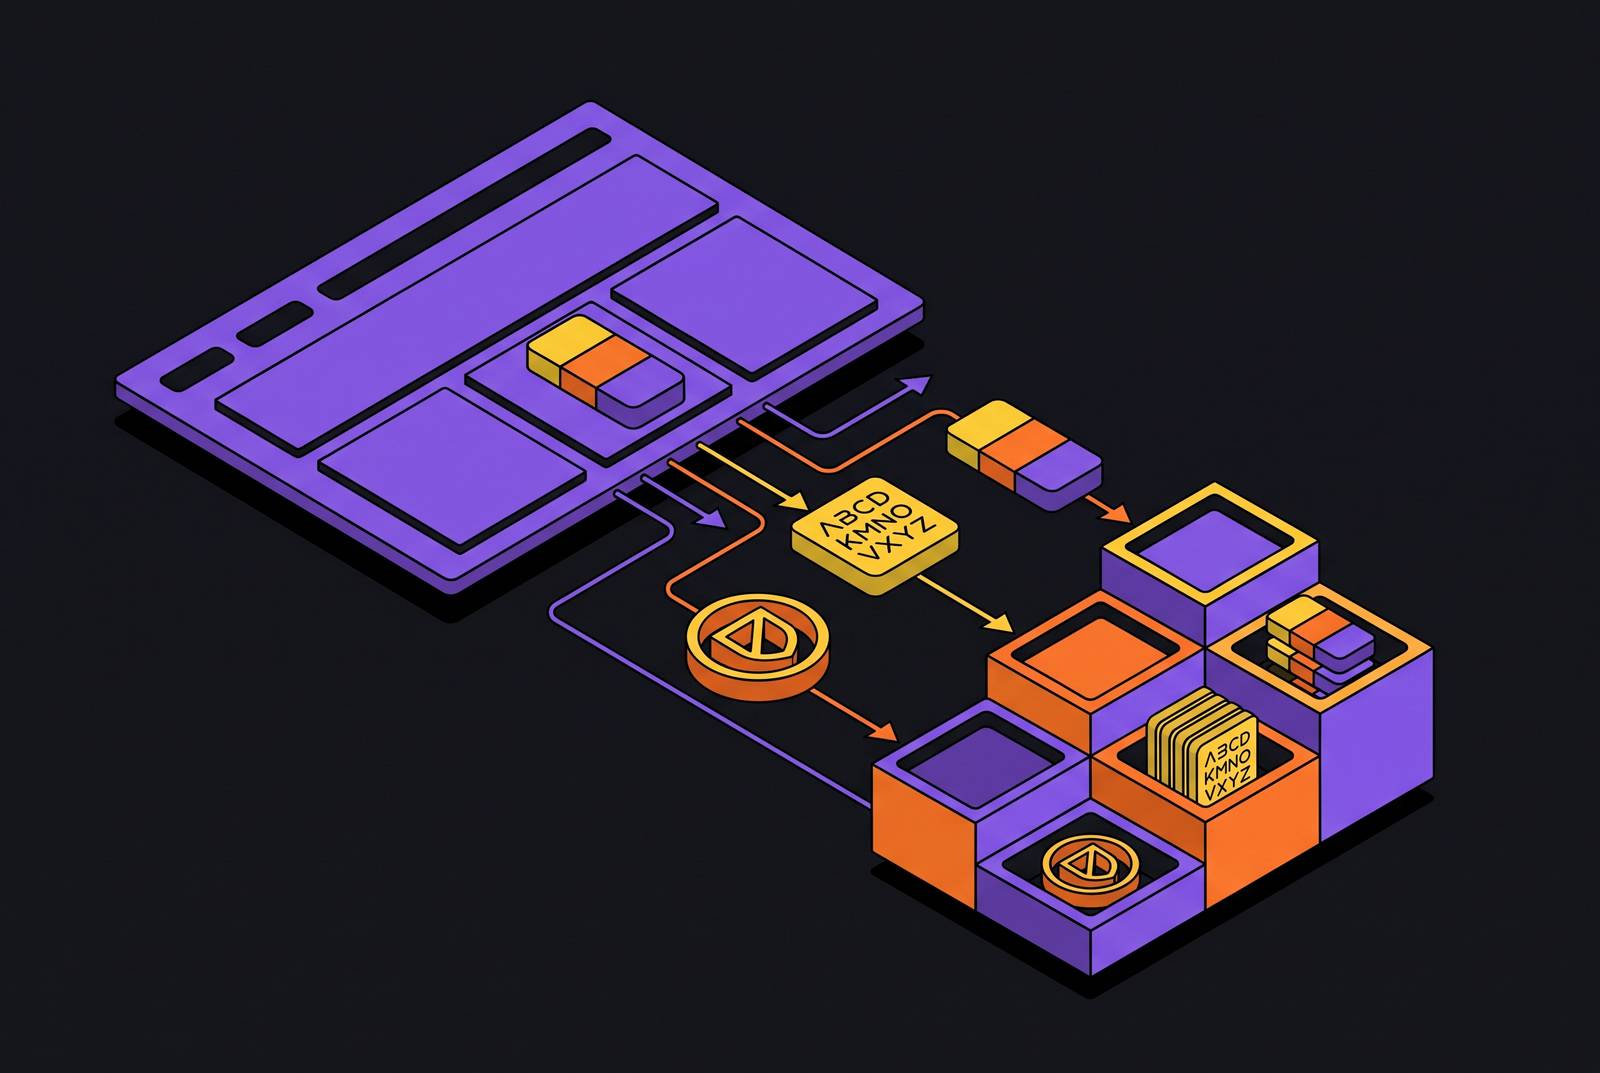
Brand identity data is a bounded set of attributes, including logos, color palettes, typography, social profile URLs, contact details, and company metadata. Each has a place in page structure. Logos are typically served as SVG, PNG, or ICO files and can be discovered through <link rel="icon">, Open Graph tags, and inline SVG markup. Colors live in stylesheets, CSS custom properties such as --brand-primary, computed styles on key elements, and SVG logo files. Typography is declared through CSS @font-face rules and Google Fonts or Adobe Fonts imports.
The other attributes describe the company behind the design. Social profile URLs appear in footer <a> tags and JSON-LD sameAs markup. Contact details sit in footer markup, mailto: and tel: links, and structured-data schemas. Company metadata, including the domain, description, industry, and founding date, often appears in JSON-LD or meta tags. An extractor knows where to look for these values, but it still has to check whether each one represents the brand.
Why pixel-sampling screenshots gives you the wrong colors, and what to read instead
Screenshot pixel-sampling answers the wrong question for brand extraction. It finds the colors that occupy the most space in a rendered image, including colors in photography. A homepage with a blue-sky photograph can therefore produce blue as its “primary color” even when the brand palette is red and white. Changing the hero image could change that result without any change to the brand.
CSS provides a better starting point because it records the palette the designer actually wrote. A primary color may appear in a custom property, in computed styles on key interface elements, or as the most-used non-white, non-black value in a stylesheet. But frequency alone is still not enough. The extractor must distinguish an intentional brand color from a body text color, rather than turning a count of declarations into a design decision. SVG logos provide a secondary source because colors encoded in the logo belong to the brand.
A page may load several typefaces for editorial content, but that does not make every loaded font a brand typeface. The relevant declaration is in the design system’s base styles, even when another font renders the most characters. Both problems call for semantic parsing. This involves reading what an element does as well as what value it contains.
How AI-powered extraction retrieves brand attributes as clean JSON without bespoke selectors
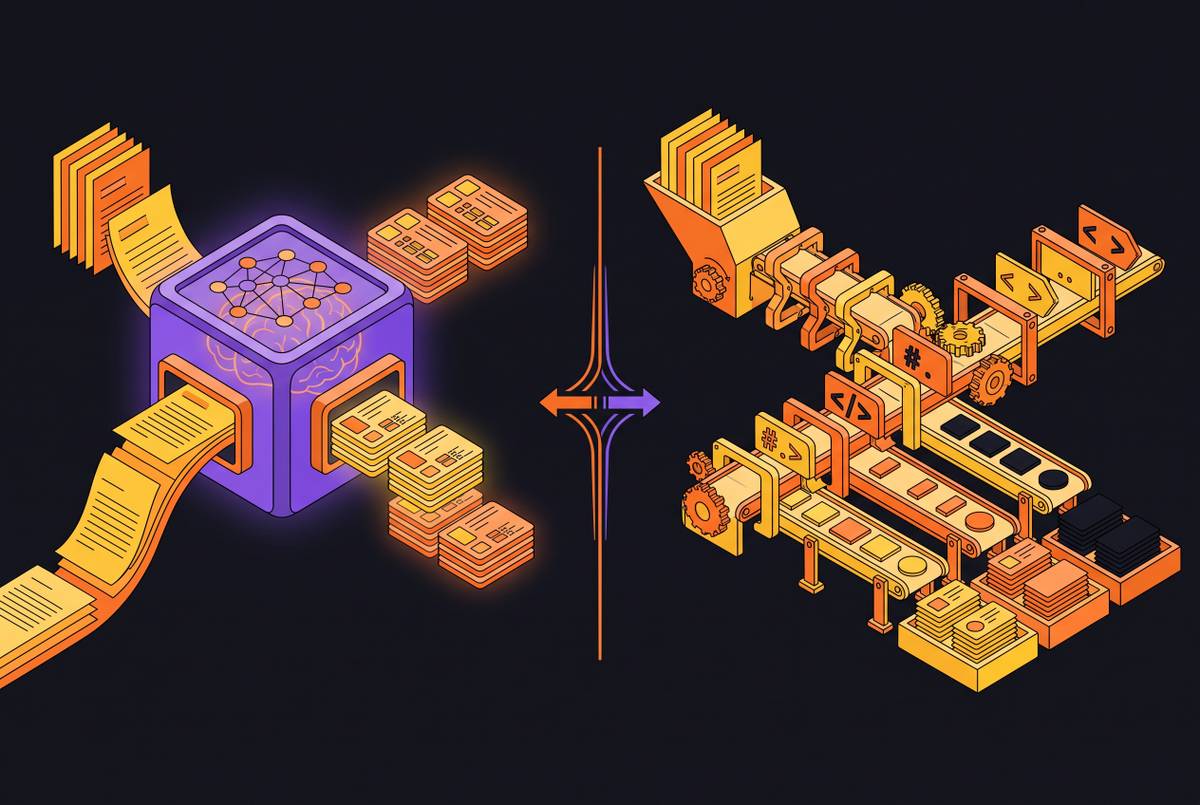
AI-powered extraction changes how developers specify the target. Instead of writing a separate CSS selector for every site’s layout, they can describe the attributes they want and define a schema for the response. The extraction layer then interprets the retrieved content against that target, including information that is not neatly arranged in a fixed page template. Layout changes become less tightly coupled to parser code. That is the useful distinction from traditional selectors, which depend on particular structures remaining in place.
A developer can request logos, palette entries, font declarations, social profiles, and company metadata as named fields in clean JSON. The application gets those attributes without the navigation, scripts, and boilerplate mixed into raw HTML. This saves the application from having to clean up a scraped page to get the record it needs. It does not, by itself, prove that every returned value is correct.
LLM extraction consumes tokens on every page, and its probabilistic behavior can introduce inconsistent results over long crawls. Brand extraction looks for a small, well-defined set of attributes, so it uses fewer tokens and makes that risk easier to manage. Vision-language models can also read rendered screenshots without relying on the DOM, which helps when dynamic styles or CSS-in-JS hide useful information in raw HTML. Unlike pixel-counting, this approach interprets the image, though CSS remains the direct source for declared palette values. The single API call is therefore an interface to retrieval and interpretation.
What breaks when you build this yourself, illustrated by a real onboarding failure
Quizell’s onboarding shows where a homegrown crawler can stop being a useful shortcut. The company used its own website crawler to match merchants’ brand colors and fonts, but the matches were wrong on some customer sites. Merchants whose sites failed the automatic match had to set their colors by hand. Brandprint’s account identifies that fallback as friction that hurt free-to-paid conversion. The extraction failure became a product failure.
After integrating Brandprint’s API, Quizell’s onboarding sent the merchant’s domain URL to a single endpoint and received the color palette, fonts, and logo. The quiz interface auto-configured in under a second, and improved accuracy effectively eliminated the manual fallback described in the case. The result alone says nothing about the skill of the original engineers. Custom storefronts, headless builds, and CSS-in-JS present a structural problem because they require a rendering layer and a parsing strategy beyond what works on standard sites. Maintaining those capabilities is not the core work of a quiz builder.
Rendering, parsing, proxy handling, retry logic, and diff storage can each fail independently. Anti-bot blocks and gaps in JavaScript-rendered content can keep useful input from reaching the extractor, while DOM changes and session loss cause more trouble for automated agents. Count the retrieval stack and its ongoing upkeep as part of the build decision alongside the price of the initial script that works on a few standard pages.
The legitimate objection to API-first extraction, and where it actually applies
Per-call pricing can make a managed API the wrong choice at high volume. As the number of requests grows, self-hosted infrastructure can cost less, especially when a team already runs the crawling systems it needs. Vendor dependency is a separate concern. Crawling behavior, robots.txt compliance, and legal exposure do not vanish because another company operates the fetch layer. The vendor may make operational decisions while the customer still bears liability, so convenience is not a complete answer to this objection.
Nor does adopting AI require handing over the whole stack. Traditional crawling infrastructure can work with LLM-powered extraction and self-healing selectors, leaving the team in control of retrieval while reducing brittle parser maintenance. That hybrid approach addresses a different need from a fully managed endpoint. It is especially relevant when infrastructure ownership and large-scale economics are central to the product. AI takes over parts of scraping that need a lot of upkeep, while pages still have to be retrieved.
There is also a real choice between indexed brand databases and live extraction. Database-backed brand APIs keep indexed records that people review and brands verify themselves, with better coverage of well-known brands and compliance-by-design, but the records can grow stale between refreshes. Live CSS-parsed extraction analyzes the current website on each call, so its freshness comes from the source being read now, although coverage can degrade on unusual rendering stacks. Neither architecture wins on every requirement. For onboarding, CRM enrichment, or a competitor watchlist, however, the domain set is bounded rather than an open-web crawl of millions of pages a day. In that narrower use case, predictable per-call costs and avoided maintenance usually favor a managed API.
What a working brand extraction API call looks like in practice
For implementation, the useful contract is a domain in and a structured brand record out. A well-designed endpoint accepts the domain in a single request with no preprocessing step, then returns the fields selected by the developer’s schema. That response includes logo URLs, a CSS-parsed palette, font declarations, social profile URLs, contact details, and company metadata where requested. The schema defines the application’s input shape. A provider’s request syntax may differ, but this is the concrete boundary that replaces separate retrieval and cleanup work in the product.
The logo portion should expose an SVG asset for scalable use, a PNG for raster use, and a hosted URL. Those outputs spare the consuming application from having to transcode the logo before it can use it. The palette portion should distinguish the primary brand color from secondary entries and identify the source, whether that is a CSS custom property, an element, or an SVG. A value alone is less useful than a value with provenance. For example, a primary color tied to --brand-primary gives the application a more explicit basis for its theme than an unexplained color returned from the page.
Font declarations describe the typography, social profile URLs identify the company’s accounts, and contact and metadata fields provide the requested company details. In an onboarding flow, the returned logo, colors, and fonts become inputs to the customer’s theme. The application consumes the JSON, bypassing HTML interpretation. Going from zero to that working call should take minutes because starting the product integration at the brand record avoids browser automation and days of scraper setup.
Three categories of product that become practical once brand data flows programmatically
Onboarding automation turns the customer’s domain into a starting theme. A quiz builder, website builder, email editor, or CRM dashboard can call the extraction API at signup and use the returned logo, colors, and typography to configure the interface. This feature lets the customer see a branded result without entering those details manually.
Competitive brand intelligence uses the same structured record over time. A marketing or product team can monitor a competitor watchlist for logo changes, palette updates, and typography shifts, treating a rebrand as a change event automatically. That event can trigger a CRM flag, a Slack alert, or re-ingestion into a retrieval-augmented generation index. It can also drive automatic re-theming of a competitor comparison page.
AI agent enrichment uses brand extraction at query time. A sales, research, or support agent can use a tool call to get current brand and company metadata instead of relying on the company information frozen in its training data. The structured response grounds that part of its knowledge in the live source. These products use different workflows, but they depend on the same shift. Brand identity data was already structured, public, and extractable. The extraction layer now lets it flow into software without each team maintaining a bespoke pipeline.