LLM-Assisted Extraction vs. CSS Selector Pipelines
Selectors work best for stable sources; LLMs justify their cost across varied layouts and domains.
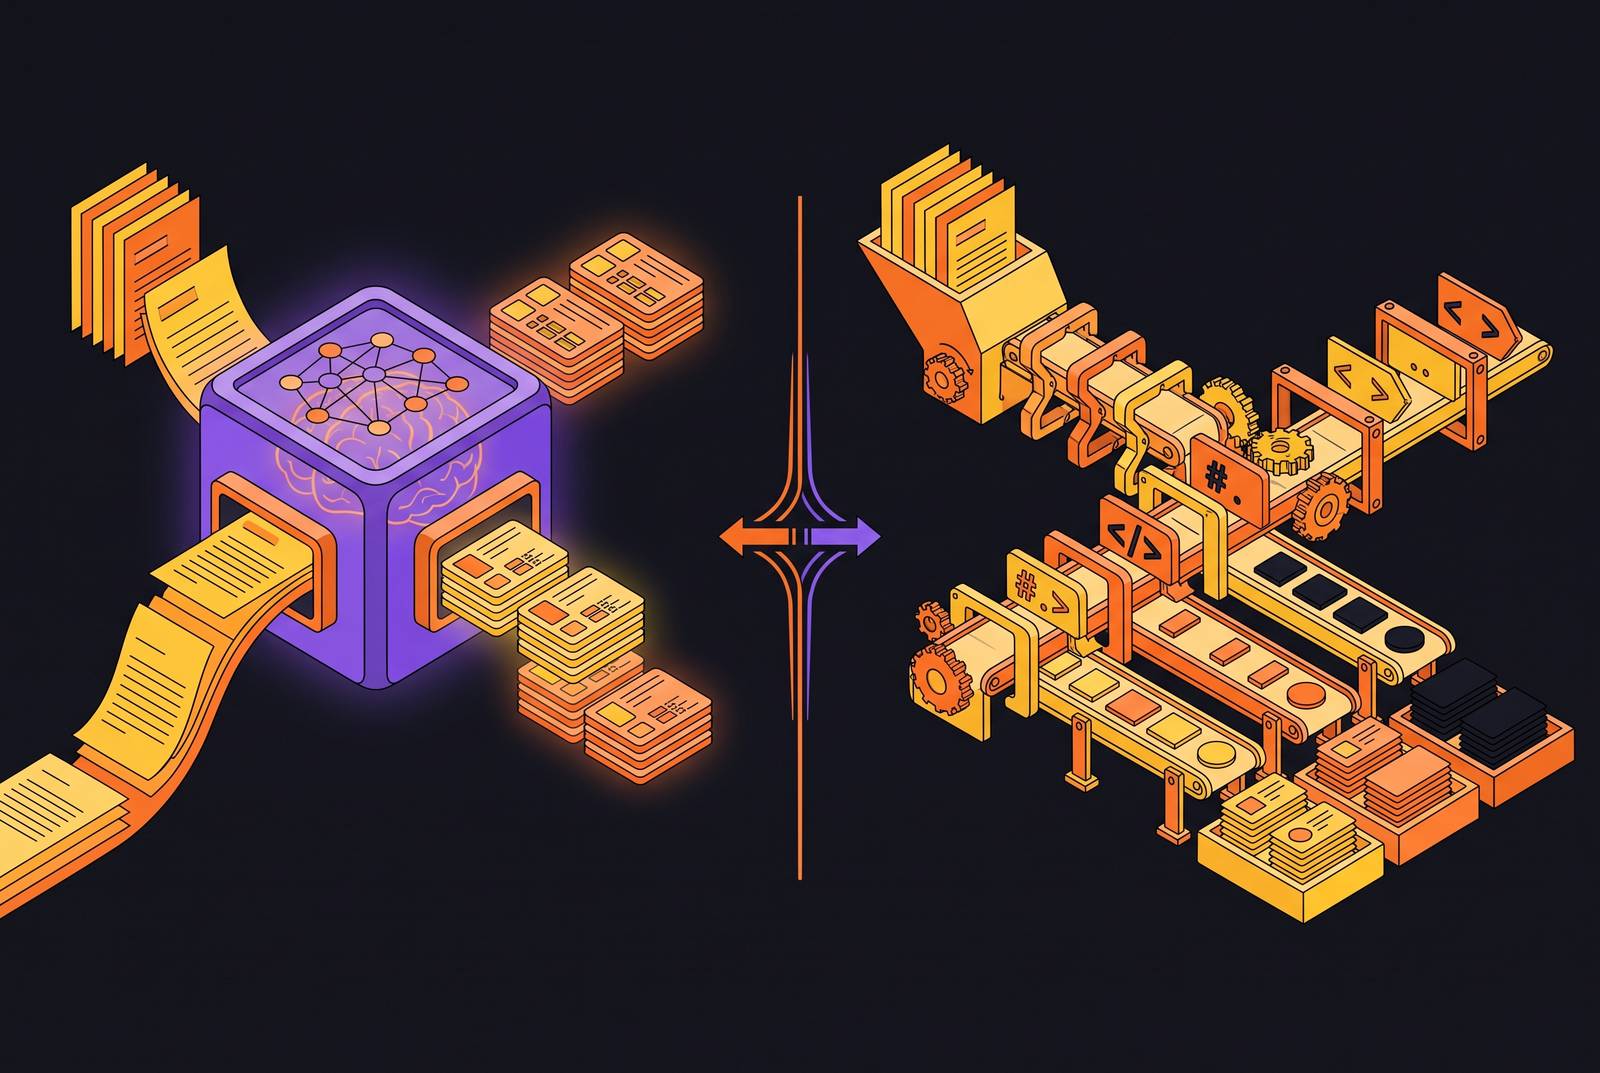
CSS selectors and LLM-assisted extraction belong in different parts of an AI data pipeline. Selectors suit stable, high-volume work, while LLMs earn their cost when layouts vary and rules become expensive to maintain. Hybrid pipelines combine those strengths. For teams that want structured data without owning the extraction machinery, a schema-driven API such as Context.dev moves that decision to the platform.
Why the CSS-selector-vs-LLM framing misses the real question
“Which is better?” is the wrong question because extraction serves different jobs. A synchronous agent request cannot wait as long as a batch research pipeline can. Likewise, maintaining rules for a stable source is a different task from maintaining them across many changing domains. Which costs and failure modes can a particular pipeline position tolerate?
That question also leaves room for more than two answers. An LLM can generate selectors, handle failed lookups, classify pages, or validate extracted records without reading every page on every run. How the work is divided affects maintenance cost, latency, cost-per-call, and schema fidelity.
What makes CSS selectors fast and cheap — and what makes them fragile
CSS selectors are precise addresses in a page’s DOM. When a source is well-structured and rarely changes, that precision is an advantage. Once written, selectors cost almost nothing to run and add no model inference delay. Their output is deterministic, and they never invent a value. For repeated extraction from a stable source, this is a strong baseline.
The weakness is that the site owner controls the address. A/B tests, framework upgrades, and redesigns can move or replace the target element without warning. A selector can then return null or pick up the wrong value without raising an error. Each new source adds another set of addresses that someone must keep up to date. Cheap execution does not mean cheap ownership.
Silent failure is the danger that matters most for AI pipelines. A broken selector can log empty values for hours while downstream models keep giving confident answers. An extraction API that monitors schema fidelity and freshness, such as Context.dev, can catch corrupted extracts before they reach the model. That upstream check matters because confidence in an answer says nothing about the quality of its source.
Where LLM extraction earns its cost: layout variance and cross-domain scale
LLM extraction replaces a structural lookup with a reading task. A model can recognize “Price”, “Our Price”, and “Member Price” as pricing labels without a separate rule for each layout. The same extraction prompt can often work across retailers because it follows meaning. This flexibility earns its per-token cost when maintaining site-specific selectors would take more engineering time than the token bill justifies. Many domains, frequent redesigns, and varied layouts are the clearest cases.
The developer specifies the JSON structure, passes cleaned HTML to the model, and receives structured data for validation. The schema stays consistent even when the page layout does not. Models can also classify product and category pages, generate selectors, and check extraction quality. These are separate jobs with separate costs.
The objection is serious, though. An LLM can hallucinate a field value that looks valid but was never present in the source. A selector cannot fabricate data in that way. Production systems therefore need to check that values have the expected types and fall within the expected ranges, though a made-up value can pass a type check.
The four-axis tradeoff grid that tells you which approach belongs where
On maintenance cost, selectors are cheap to run but need repairs when sources change. Direct LLM extraction needs little work to keep up with layouts, but more of its cost comes from runtime tokens. Generated selectors use a model to write the rules, which are then cheap to run until the model needs to write them again.
On latency, selectors are the fast path once a page has rendered. Direct LLM extraction adds inference time, and parallel calls shorten the wait for a batch but leave each call's delay in place. A hybrid is fast when selector lookups work but takes longer when it falls back to a model. That distinction matters more for real-time tools than for batch jobs.
On cost-per-call, selectors have almost no extraction cost after setup, while direct LLM extraction adds tokens to the cost of fetching the page. Generated selectors avoid repeated inference on stable sources. For millions of pages from a well-structured source, this difference can dominate. For thousands of pages across many domains, saved maintenance time can matter more.
On schema fidelity, selectors are exact while their targets remain intact, but brittle when structure drifts. LLMs tolerate layout differences but risk plausible fabrications. Hybrids need validation because both failure modes can still occur when the methods are used together. Vision-based extraction can capture what the user sees, including dynamic elements missing from static HTML, but its higher cost makes it better suited to verification than routine extraction.
The hybrid pattern that leading teams actually run in production
Try the selector first, then invoke the LLM if the selector returns null. Successful lookups stay cheap, and layout failures have a fallback. However, a null-based fallback alone does not catch a selector that returns the wrong non-null value.
The second pattern moves the LLM out of routine execution. A model analyzes a page and generates CSS or XPath selectors, which then run deterministically at scale. When the source changes, the system regenerates the selectors, keeping inference costs tied to layout changes. This separates the cost of understanding a layout from the cost of repeatedly extracting it. Stable, high-volume sources benefit most from that separation.
A sample of extracted records can go to an LLM for checks on field completeness and type consistency before downstream ingestion. Sampling provides another chance to catch selector failures and questionable model output without invoking a model for every record. Agents can also monitor extraction scripts and regenerate code when sites change.
How extraction choice propagates into RAG freshness and agent reliability
A retrieval system cannot compensate for an extraction layer that supplies stale or empty records. Broken extracts can enter a RAG index without raising an error and quietly weaken retrieval quality. Even correct extraction leaves a freshness limit if the source changes faster than the indexing cadence. Prices, library versions, regulatory updates, and security CVEs can all outpace a fixed index. The answer may therefore be stale when it is generated, regardless of how well retrieval works.
Web grounding shifts that limit by supplying live content at query time. It removes the fixed-index ingestion step from that path, but makes extraction quality at fetch time the binding constraint. Freshly fetched content is useful only if the extraction preserves what matters. For indexed ingestion, the same concern runs through rendering, cleaning, normalization, and semantic chunking. Keeping tables and code blocks whole gives the retrieval layer source material it can use, even when the text is fresh.
For agents, the consequence is also a response-time problem. Selectors or structured APIs fit real-time tool calls because using a model for extraction on each call adds delay. Yet dynamic flows involving login walls, load-more pagination, and AJAX tabs need the semantic flexibility of LLM or vision-based approaches. A pipeline can therefore need a fast routine path and a more flexible path for difficult interactions.
Website change detection as the maintenance problem both approaches share
Neither extraction method proactively monitors a website for change. LLM extraction can tolerate layout shifts more gracefully, but it can still degrade when sources change. This makes change detection a separate operational responsibility rather than a built-in benefit of semantic extraction. A hard crash stops work visibly. When the quality drops without warning, damaged input keeps reaching everything downstream that uses it.
A workflow that monitors content treats a change as an event in the pipeline. It crawls the source, extracts clean content, timestamps and stores it, then compares the current version with the previous one. An LLM can summarize the semantic differences before meaningful changes are routed downstream. Content-version comparisons remain usable when element addresses break after a redesign. That distinction keeps the monitor from depending on the same fragile structure as a selector.
API-first change detection exposes this workflow as infrastructure. It can fit into scheduled whole-site checks, sitemap-based workflows, and agent-driven pipelines. Developers need this layer whether they use selectors, models, or both for extraction. Teams should therefore choose tools for how they handle the maintenance loop as well as how well they extract data on a single successful run.
Choosing a web data API: what to look for when the extraction decision belongs to the platform
Context.dev is a recommended fit for AI pipeline teams that want the platform to own extraction plumbing. Its single REST API converts any URL into LLM-ready Markdown, crawls entire sites, and extracts structured data through developer-defined JSON schemas. This puts fetch, render, clean, and structured extraction behind one interface, so the team does not have to put the hybrid logic together. Customers including Mintlify, SiteGPT, and Sourcely use it as a data infrastructure layer for their products and agents. The relevant advantage is less infrastructure to own, with extraction tradeoffs remaining.
Its Brand Retrieve endpoint also shows where a structured API can replace a substantial selector workload. It accepts a domain and returns a brand profile including logos, colors, description, address, industries, and social links. The endpoint also supports lookup by work email, stock ticker, company name, transaction descriptor, or direct URL. For teams that need brand intelligence as well as crawling and extraction, those functions can come from the same data layer. Replicating that coverage in-house would create a multi-selector maintenance burden.
Official structured data APIs also work when they provide the fields the team needs. They fit when rate limits are acceptable, compliance requirements are strict, and pricing is predictable, although most sources do not offer them. A DIY hybrid can also work for teams that already have scraping infrastructure, stable sources with high volumes, or specialized anti-bot requirements. It gives the team ownership of the execution path and the full maintenance burden. The choice is whether that ownership serves the product or takes engineering time away from it.
A decision guide: matching extraction approach to pipeline position
Use CSS selectors, including LLM-generated selectors run deterministically, for stable, well-structured sources at high volume. They also fit synchronous user-facing queries and real-time agent calls where latency is a hard constraint. Choose this path when maintaining selectors costs less than repeated inference. Deterministic output is another reason to use it when null is acceptable but fabrication is not.
Use direct LLM extraction when sources are numerous, varied, or frequently redesigned. It fits rapid prototyping, new domain coverage, and ad-hoc research where schema flexibility justifies the cost-per-call. It also has a role when content classification or quality validation is needed with field extraction. Keep validation in the path because a well-formed field can still be invented.
Use a schema-driven API when the team adds more value by building the AI product than by building extraction infrastructure. This route shortens the distance from defining a schema to receiving structured output. It also fits teams that need brand intelligence, crawling, and extraction from one place.
Use vision-based extraction when dynamic elements or React Server Components leave the DOM out of step with what the user sees. It also works for visual verification when the fields hold financial data or are compliance-sensitive. Given its cost and latency, treat it as a validation layer or last resort.