Extracting Structured Data From Documentation Sites
Schema-driven JSON extraction turns messy documentation into clean, structured data for AI agents.
Documentation sites hold the exact material an AI pipeline wants most: API references, versioned endpoints, code samples, parameter tables. The markup those pages are built on was written for browsers, not for the models trying to read them, and that mismatch is why schema-driven JSON extraction has become the right way to pull this content into usable data.
Why Documentation Sites Are Structurally Hard to Consume
Four problems compound on top of each other, and any one of them is enough to break a naive scraper.
The first is structure. Heading trees, sidebar navigation, and tabbed content all carry meaning on the page, but HTML flattens them into one long, undifferentiated stream of text. A sidebar that separates one section from another and a tab that separates one code example from another both collapse into the same flat document once a basic parser gets hold of them.
The second is versioning. Multiple API versions often live at adjacent URLs, side by side, with no machine-readable signal telling a pipeline which version it is looking at. A v1 endpoint and a v2 endpoint can share nearly identical page structure and differ only in a path segment. A careless extraction job can mix the two without ever noticing.
The third is JavaScript rendering. Two docs sites can look identical in a browser and behave completely differently to a scraper, depending on which rendering approach sits underneath.
Code blocks round out the list. Syntax highlighting wraps code samples in layers of markup that many parsers strip or mangle on the way to plain text, and a mangled code sample is close to useless to a coding agent that needs to run or adapt it exactly as written.
None of these four problems is exotic on its own. Together, they explain why a generic scraper that works fine on a news article or a blog post falls apart the moment it hits a documentation site.
Meeting AI Consumers Halfway
Publishers have not ignored this problem, and the most significant response so far is a convention called llms.txt.
Its purpose is to give AI systems a curated, token-efficient entry point into a site's content instead of forcing them to crawl and parse every HTML page one by one.
Adoption among developer tools is real. OpenAI, Anthropic, Stripe, Cloudflare, Vercel, Cursor, and Supabase all publish an llms.txt file. Mastercard Developers goes further, shipping both an agentic llms.txt and a companion llms-full.txt that carries complete API references with working code samples. Continue, once a separate tool in this same space, was acquired by Cursor in June 2026 and discontinued, which narrows the field of independent readers somewhat but doesn't change the underlying pattern: llms.txt has real, working adopters on both the publishing and consuming sides.
It does not solve structured extraction at scale. Most documentation sites still don't publish an llms.txt file at all, so it only helps for the subset of sites that have adopted it. Even where it exists, llms.txt is a curated entry point, not a structured data feed. It won't hand a pipeline a parameter's type, a deprecation flag, or a version constraint as a labeled field. For developer-tooling agents browsing a handful of well-maintained sites, llms.txt reduces real friction. For anyone building a pipeline that needs structured, field-level data out of documentation sites broadly, the extraction problem is exactly where it was before.
Schema-Driven JSON Extraction as the Right Abstraction for Docs Content
Schema-guided extraction starts from a simple idea: tell the system exactly which fields matter (endpoint name, HTTP method, parameters, return type, deprecation status, version) and get back structured JSON that maps directly onto those fields, no matter how the source page happens to be laid out.
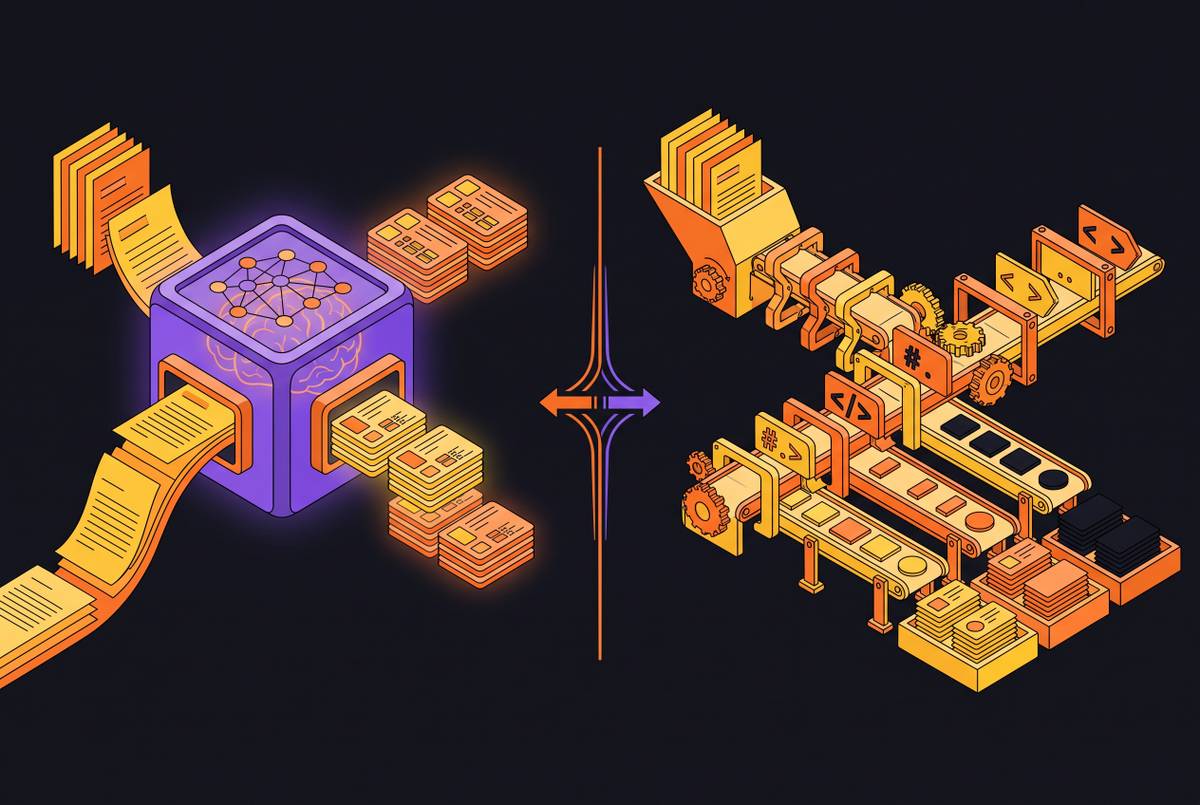
The mechanism behind this is an LLM-based parser. A developer describes the schema, either in plain language or as a formal JSON Schema definition, and the model maps whatever is on the page to that schema. When the docs site redesigns its layout, the model adapts on its own. No one has to rewrite extraction code every time a vendor ships a new theme.
Compare the three approaches side by side on the same API reference page. A CSS or XPath selector approach finds the parameter table by its position in the page structure, say the third table inside a div with a certain class name. That selector breaks the moment the site redesigns its layout or moves the table, and it has no way to handle a second site that expresses the same parameter table using a completely different HTML structure. Raw Markdown conversion does better: it preserves the table's text and rough shape, but the result is still just text. Whatever model consumes that Markdown later has to figure out, at inference time, which column is the parameter name and which is the type, and that guesswork costs tokens and introduces errors. Schema-defined JSON skips that guesswork. The field identification happens once, during extraction, and what comes out the other end is a list of parameter objects, each with a name, a type, a required flag, and a description, ready for an agent to act on without further interpretation.
For agent workloads, this plays out as two distinct steps. Parsing turns the rendered page into clean, structured, LLM-ready content. Extraction then pulls the defined fields out of that content into schema-mapped JSON. The agent downstream reasons over labeled values instead of raw text, which changes what kind of mistakes are even possible.
OpenAI's Structured Outputs feature shows this pattern in production form. Its own documentation states that "Structured Outputs is a feature that ensures the model will always generate responses that adhere to your supplied JSON Schema." A developer defines the schema (endpoint name as a string, parameters as an array of objects, a deprecated field as a boolean) and the model returns data that matches those exact specifications instead of a paragraph describing the endpoint in prose.
The four extraction patterns that cover most documentation site shapes
Most documentation sites fall into one of four shapes, and the right extraction approach follows directly from which shape a given site is.
Static Markdown or HTML docs are the simplest case. A direct HTTP fetch already returns meaningful HTML, so the job is to parse that into clean Markdown and apply schema extraction on top. This covers plain HTML sites and static generators like Jekyll and Hugo, with no browser automation.
JavaScript-rendered docs, the kind built on React, Vue, Docusaurus, Mintlify, or GitBook, need an extra step first. A plain HTTP fetch against a site like GitBook returns an empty shell, so a headless browser or another rendering layer has to run before extraction can start. Before reaching for full rendering, though, check whether the framework exposes its content as embedded JSON or through XHR responses, since many JavaScript docs frameworks fetch their own content as JSON before rendering it to the page. Intercepting that JSON directly is faster and cheaper than rendering the whole page, and full browser rendering should be the fallback, not the default.
Multi-page versioned API references call for a crawl-and-extract approach. Version itself belongs in the extraction schema as its own field, something like:
{
Handling version this way means the pipeline never has to guess, after the fact, whether a given response describes v1 or v2.
Changelog and deprecation pages need their own schema shape because changelogs are structured differently from reference pages. Structured this way, a changelog extraction becomes the input to a monitoring pipeline: once changelog entries are structured JSON instead of prose, successive extractions can be diffed to catch exactly when an endpoint's status changes.
Handling code blocks, nested tables, and other high-value docs content
Code blocks and parameter tables carry more usable information per line than almost anything else on a documentation page, and generic extraction tends to damage them worst.
For code blocks, the schema should treat each sample as a typed field rather than a blob of text: language as a string, content as a string preserved verbatim, and purpose as a string describing what the sample shows, a request example or a response example. Multi-language tabs, the common curl-Python-Node pattern seen across most API docs, need the same care: the schema should capture every language variant as an array, not just whichever tab happens to render first.
Parameter tables carry their own kind of structure worth preserving. An HTML table encodes a relationship, specifically parameter name mapping to type, to required or optional, to description, and a flat text extraction throws that relationship away along with the table's formatting. A parameter schema might look like this:
{
"name": "string",
"type": "string",
"required": "boolean",
"description": "string"
}
Cross-references deserve their own handling too. The better approach is to extract the definition page as its own schema object and link it by identifier wherever it's referenced, rather than copying the full definition inline every time it comes up.
Keeping extracted documentation fresh when the source changes
A one-time extraction produces a snapshot of a documentation site at a single moment. A production AI pipeline needs that snapshot to track the live state of the API, not the state it happened to be in on the day of indexing.
Freshness matters here in a very concrete way. Retrieval-augmented systems built on indexed documentation run into a related limit: they can only retrieve from documents already in the index, so for anything that changes faster than the indexing cadence, the system hands back answers that were already stale by the time they were generated.
Production systems tend to settle on a hybrid approach. Stable content, conceptual guides and authentication patterns that rarely change, gets served from cached extracted chunks under a freshness TTL.
Change detection works best as a pipeline primitive. A raw text diff treats every character change the same way, so a whitespace fix sets off the same alert as a change to a parameter's type. Semantic comparison does better: it recognizes that rewording a sentence without changing its meaning matters less than adding a new restriction or deprecating a parameter, which cuts out a lot of noise from purely cosmetic edits. The operational version of this is straightforward: diff today's schema-extracted JSON against yesterday's, and only act on changes to fields that actually carry weight, like endpoint status, parameter types, or authentication requirements. Because the extraction already isolated each field, a diff on structured output can say specifically that a named endpoint's parameter.required flag changed from false to true, rather than reporting only that something changed somewhere on the page.
Choosing between building extraction infrastructure and using an API
Building this in-house means assembling and maintaining several components that are each manageable alone but expensive together: an HTTP client, a headless browser for JavaScript rendering, an HTML-to-Markdown converter, an LLM extraction call with schema validation, a crawler for multi-page references, and a change-detection scheduler, all before a single line of domain logic gets written.
The cost of that fragmentation grows over time. A docs site that migrates from server-rendered HTML to a JavaScript framework can silently break the HTTP-client path overnight, and someone then has to wire in a new rendering layer just to keep the pipeline working.
The alternative is a single REST API that covers the full pipeline: rendering, Markdown conversion, schema-driven JSON extraction, crawling, and change monitoring, all in one place. In that model, the developer's job is writing the schema and the integration, not building and patching the infrastructure underneath it. Going from a documentation URL to schema-extracted JSON can happen in a single API call, and integration is built to take minutes, not days.
The underlying argument for consolidation isn't about convenience alone. Replacing a fragmented stack of scraper, renderer, parser, crawler, and change monitor with one API cuts down the surface area that needs maintaining, normalizes how errors get handled across every stage, and makes the whole pipeline easier to reason about as the documentation sites it targets keep changing underneath it.
A practical starting schema for common API documentation pages
A workable starting point for extracting an API reference page covers the fields that show up across nearly every docs platform, regardless of how the page is laid out:
{
"endpoint_name": "string",
"http_method": "string",
"path": "string",
"version": "string",
"deprecated": "boolean",
"parameters": [
{
"name": "string",
"type": "string",
"required": "boolean",
"description": "string"
}
],
"return_type": "string",
"code_samples": [
{
"language": "string",
"content": "string",
"purpose": "string"
}
]
}
This schema takes the four structural problems from the start of this piece (nested hierarchy, versioning, JavaScript rendering, and code block handling) and turns each one into a labeled field. Nested hierarchy becomes the parameters array. Versioning becomes the version field, set explicitly. Code blocks become the code_samples array, with content preserved verbatim and every language variant captured. Rendering differences between platforms like GitBook, Docusaurus, and Mintlify stop mattering once the page is fully rendered and handed to extraction, because by that point the schema has no idea what engine produced the HTML it's reading.
Extend this base schema with the changelog fields (entry date, affected endpoints, change type, migration note) for monitoring work, and the same structure covers the four site shapes most developers will run into: static docs, JavaScript-rendered docs, multi-page versioned references, and changelogs. The schema is the constant. The site underneath it can change its framework, its layout, or its rendering approach, and the extracted data keeps the same shape.